
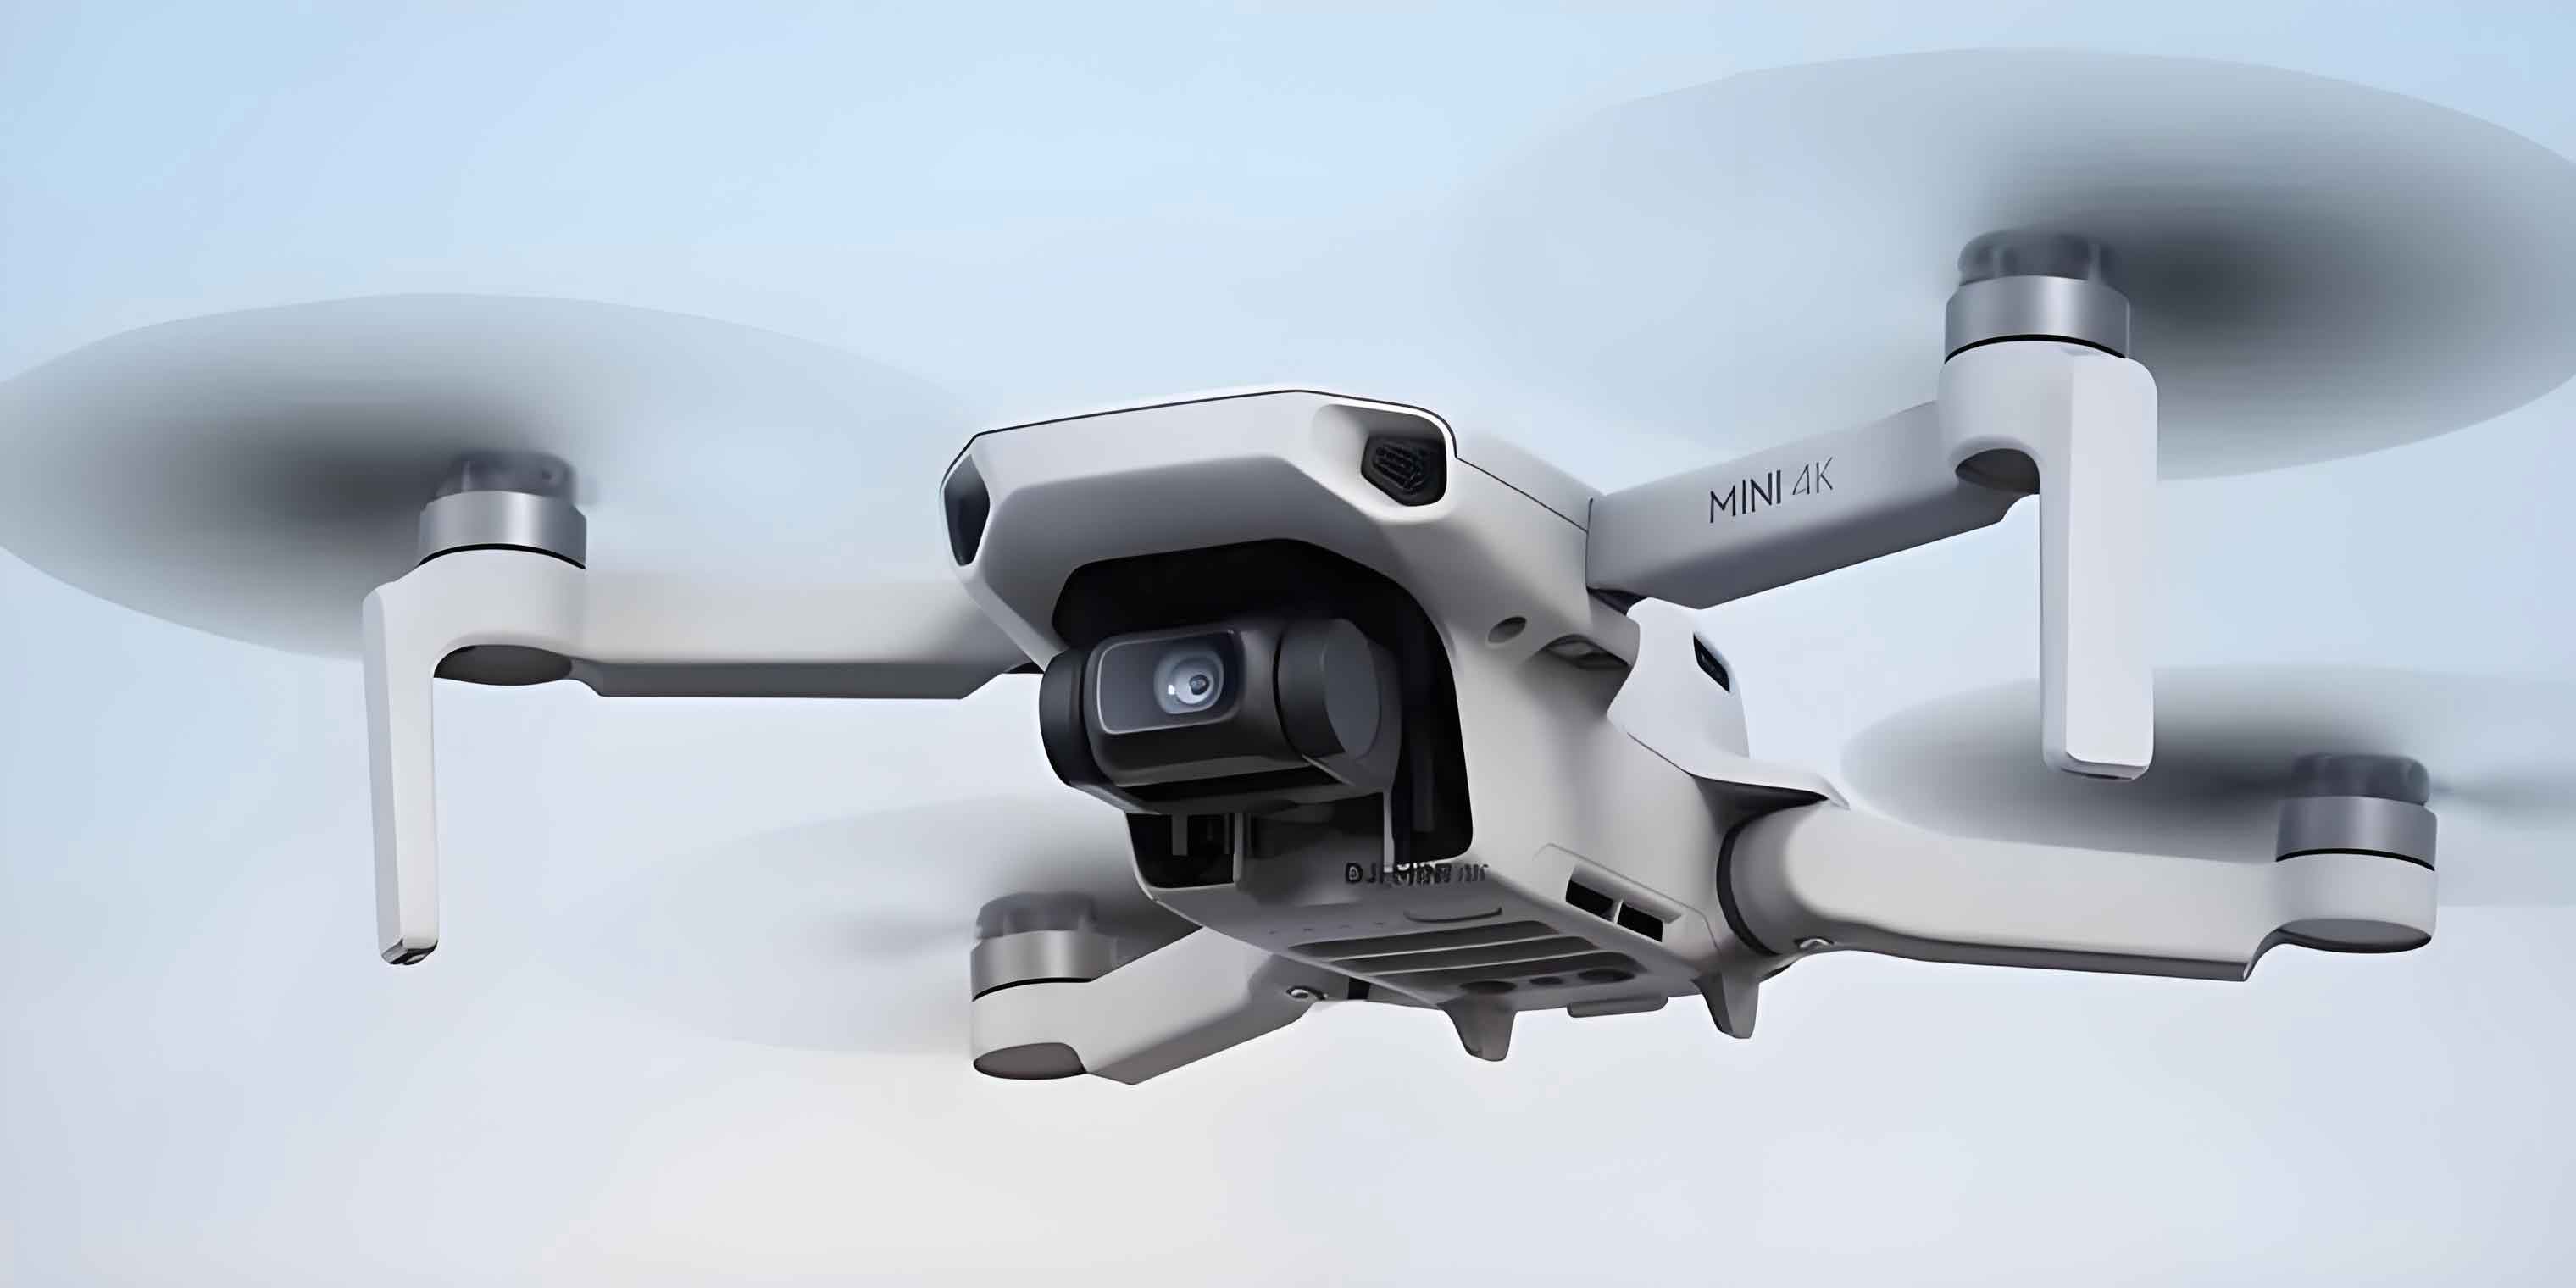
In recent years, the rapid advancement of microelectronics and embedded technologies has greatly accelerated the development of unmanned aerial vehicle (UAV) techniques. UAVs, especially quadrotors, have been widely applied in civilian and military fields such as aerial photography, security surveillance, path planning, and autonomous navigation. Among the core enabling technologies, visual target tracking plays an indispensable role for UAVs to perform intelligent tasks like following a moving object or avoiding obstacles. However, deploying a high-accuracy deep learning model on a resource-limited UAV platform remains a challenging issue. The on-board computing devices are constrained by strict power budgets and payload capacity, making it difficult to run heavy convolutional neural networks. Meanwhile, UAV tracking scenarios are highly dynamic — the target often appears small, moves fast, suffers from severe scale changes, occlusion, background clutter, illumination variation, and camera motion. These factors cause tracking drift or even complete failure. Therefore, designing a real-time and robust UAV target tracking algorithm is still an open problem.
To tackle these challenges, I have designed a complete quadrotor UAV target tracking system based on deep learning. The main contributions of my work are summarized as follows. First, I propose a novel lightweight tracking algorithm named SiamLT that combines a Siamese network with an improved Vision Transformer for multi-scale feature fusion and correlation matching. Second, I investigate the edge deployment of the proposed algorithm including model quantization and operator optimization on different NPU platforms. Third, I construct a real quadrotor UAV platform and verify the tracking system in both normal and complex scenes. The experimental results demonstrate that the proposed system achieves high accuracy and real-time performance on embedded devices, fulfilling the practical requirements of UAV tracking.
1. Related Work
Target tracking algorithms can be broadly divided into correlation-filter-based methods and deep-learning-based methods. Correlation filters such as KCF and MOSSE exploit the fast Fourier transform to compute the response map between the target template and the search region. These methods achieve high frame rates on CPUs, but they often fail under severe deformation, occlusion, fast motion, and background clutter. With the advent of deep learning, convolutional neural networks (CNNs) have been introduced into visual tracking. The fully-convolutional Siamese network SiamFC formulates tracking as a similarity matching problem and achieves a good trade-off between speed and accuracy. Later, SiamRPN incorporates a region proposal network into the Siamese framework, enabling accurate bounding box regression. Many subsequent works, including SiamCAR, SiamBAN, and SiamGAT, further improve the discriminative power of Siamese trackers.
However, CNNs are inherently limited in capturing long-range dependencies and global context. Recently, Vision Transformer (ViT) has shown strong performance in image classification and object detection by modeling global relationships through self-attention. Transformer-based trackers such as SwinTrack, TransT, and MixFormer achieve state-of-the-art accuracy. Nevertheless, the computational cost of Transformer is usually too high for embedded platforms. To address this problem, some lightweight trackers have been proposed for UAV scenarios. For instance, HiFT utilizes a hierarchical feature transformer, while TCTrack introduces temporal context to improve aerial tracking. SiamAPN++ uses a lightweight attention aggregation network and runs in real time on NVIDIA Jetson AGX Xavier. Even so, most existing algorithms still suffer from either insufficient accuracy in complex scenes or excessive computational overhead.
For UAV platforms, the key requirements are: low model parameters and FLOPs, fast inference on CPU or NPU, and strong robustness to small targets, scale variation, occlusion, and viewpoint changes. In this work, I design SiamLT to meet these requirements by combining a lightweight CNN backbone with an efficient Transformer-based fusion network.
2. Proposed Method: SiamLT
The overall architecture of SiamLT is illustrated in the following conceptual diagram (the original figure is not reproduced here for brevity). It follows a Siamese structure with two branches that share weights: a template branch and a search branch. The input template image is of size 80×80 pixels, and the search image is of size 320×320 pixels. Both branches first pass through a lightweight backbone network to extract multi-scale feature maps. These features are then fed into a multi-scale feature fusion network built with the proposed LMFF-Trans blocks. Finally, the fused template and search features are processed by a correlation layer named DW_LMFF and a classification/regression head to output the target bounding box.
Mathematically, let the template feature be denoted by \(\mathbf{X}_t\) and the search feature by \(\mathbf{X}_s\). The tracking process can be expressed as:
$$
(\mathbf{X}_t, \mathbf{X}_s) = \text{Backbone}(\mathbf{I}_t, \mathbf{I}_s),
$$
$$
\mathbf{F}_t = \text{Fusion}(\mathbf{X}_t), \quad \mathbf{F}_s = \text{Fusion}(\mathbf{X}_s),
$$
$$
\mathbf{R} = \text{Head}\big(\text{DW\_LMFF}(\mathbf{F}_t, \mathbf{F}_s)\big),
$$
where \(\mathbf{I}_t\) and \(\mathbf{I}_s\) are the template and search images, and \(\mathbf{R}\) represents the classification score map and regression offsets.
2.1 Lightweight CNN Backbone
To reduce the computational cost while maintaining sufficient feature extraction capability, I adopt GhostNet as the backbone network. GhostNet introduces the Ghost module which partitions the output feature maps into two parts: one part is generated by a small number of standard convolutions, and the remaining part is produced by cheap linear transformations of the first part. This effectively reduces the redundancy in the feature maps and lowers the computational cost. Figure below shows the comparison between a standard convolution and the Ghost module (not reproduced here). The Ghost module first uses a pointwise convolution to generate a compact feature map, then applies a set of depthwise convolutions (denoted as \(\Phi_1, \Phi_2, \dots, \Phi_k\)) to obtain ghost features, and finally concatenates both parts.
The detailed structure of the backbone used in SiamLT is listed in Table 1. The input image is of size 320×320×3. After several convolution and Ghost bottleneck layers, I extract three groups of features from different stages, denoted as \(F_1\), \(F_2\), and \(F_3\). These features have spatial strides of 4, 8, and 16 with respect to the input, respectively, and channels of 40, 80, and 160.
| Input size | Operation | Stride | Output channels | Feature label |
|---|---|---|---|---|
| 320×320×3 | Conv | 2 | 16 | – |
| 160×160×16 | Ghost | 1 | 16 | – |
| 160×160×16 | Ghost | 2 | 24 | – |
| 80×80×24 | Ghost | 1 | 24 | – |
| 80×80×24 | Ghost | 2 | 40 | – |
| 40×40×40 | Ghost | 1 | 40 | – |
| 40×40×40 | Ghost | 2 | 80 | \(F_1\) |
| 20×20×80 | Ghost | 1 | 80 | – |
| 20×20×80 | Ghost | 1 | 80 | – |
| 20×20×80 | Ghost | 1 | 80 | – |
| 20×20×80 | Ghost | 1 | 112 | – |
| 20×20×112 | Ghost | 1 | 112 | – |
| 20×20×112 | Ghost | 2 | 160 | \(F_2\) |
| 10×10×160 | Ghost | 1 | 160 | – |
| 10×10×160 | Ghost | 1 | 160 | – |
| 10×10×160 | Ghost | 1 | 160 | – |
| 10×10×160 | Ghost | 1 | 160 | \(F_3\) |
In Table 1, “Conv” represents a standard convolutional layer, and “Ghost” refers to a bottleneck structure composed of Ghost modules. The feature labels \(F_1, F_2, F_3\) are used in the subsequent fusion network. This backbone significantly reduces the number of parameters and FLOPs compared with commonly used backbones like AlexNet or ResNet.
2.2 LMFF-Trans: Lightweight Multi-scale Feature Fusion Transformer
Traditional FPN-based fusion simply sums up features from different scales after upsampling, which may destroy the original semantic information. To better fuse multi-scale features, I propose a lightweight network named LMFF-Trans (Lightweight Multi-scale Feature Fusion Transformer). The design is inspired by the Vision Transformer encoder, but with a crucial modification to reduce the computational cost of self-attention.
The standard multi-head self-attention (MHSA) can be formulated as:
$$
\text{Attention}(\mathbf{Q}, \mathbf{K}, \mathbf{V}) = \text{softmax}\left(\frac{\mathbf{Q}\mathbf{K}^T}{\sqrt{d_k}}\right)\mathbf{V}.
$$
Given an input feature \(\mathbf{X} \in \mathbb{R}^{H \times W \times C}\), the computational complexity of MHSA is:
$$
\Omega(\text{MHSA}) = 2HWC^2 + 2(HW)^2 C,
$$
where \(H\) and \(W\) are the height and width of the feature map, and \(C\) is the channel dimension. The quadratic term \((HW)^2\) grows rapidly with the spatial size, making standard attention too expensive for high-resolution features.
In LMFF-Trans, I split the input feature into two parts: \(\mathbf{X}_Q\) and \(\mathbf{X}_{KV}\). The query matrix is generated from \(\mathbf{X}_Q\) without downsampling, while the key and value matrices are generated from \(\mathbf{X}_{KV}\), which is first compressed by a pooling operation with a stride factor \(r\). The compression operation \(p(\cdot)\) is illustrated in the original figure: the input feature is reshaped, pooled, and then projected. This reduces the number of key/value vectors from \(HW\) to \(hw = HW / r^2\), while keeping the output dimension unchanged because the number of query vectors remains \(HW\).
The modified attention is computed as:
$$
\mathbf{Q} = \mathbf{X}_Q \mathbf{W}_Q, \quad
\mathbf{K} = p(\mathbf{X}_{KV}) \mathbf{W}_K, \quad
\mathbf{V} = p(\mathbf{X}_{KV}) \mathbf{W}_V,
$$
The computational complexity becomes:
$$
\Omega(\text{LMFF-MHSA}) = 2HWC^2 + 2hwC^2 + 2HWhwC,
$$
where \(hw \ll HW\). This compression significantly reduces the computational cost, allowing the Transformer to operate at high resolutions.
For multi-scale fusion, LMFF-Trans accepts multiple input features \(\{\text{Input}_1, \ldots, \text{Input}_n\}\) of different spatial sizes. Each input is compressed with a distinct compression factor \(r_i\). The compressed features are concatenated along the channel dimension to form the key/value source. The query source is chosen as one of the inputs (the largest one by default) to preserve the output resolution. The attention output is then processed by a feed-forward network (MLP) with residual connections and layer normalization.
The structure of a single LMFF-Trans block is shown in the original figure. In SiamLT, I build a Fusion Block that consists of one cross-attention LMFF-Trans layer followed by three self-attention LMFF-Trans layers. The cross-attention layer takes \(F_1, F_2, F_3\) as inputs and uses them to generate both queries and key/values. The subsequent self-attention layers refine the fused feature. The number of Fusion Blocks can be adjusted to balance speed and accuracy. In the default configuration, I use \(N=2\) Fusion Blocks.
The forward computation of a Fusion Block can be expressed as:
$$
\begin{aligned}
\text{output}_1 &= \text{LT}_1\big((F_1, F_2, F_3), (4,2,1), F_3\big), \\
\text{output}_n &= \text{LT}_n\big((\text{output}_{n-1}, \text{output}_{n-1}), (2), \text{output}_{n-1}\big), \quad n=2,3,4,
\end{aligned}
$$
where \(\text{LT}_n\) denotes the \(n\)-th LMFF-Trans block, the tuple before the arrow indicates the key/value source and compression factors, and the last argument is the query source.
The multi-scale fusion network enhances the model’s ability to handle small targets and scale variations, as verified by the visualization of attention maps shown in the original figure. Without the compression operation, the attention map is scattered because the scale mismatch among features makes fusion difficult. With LMFF-Trans, the attention map concentrates on the target region, producing more accurate classification results.
2.3 Correlation Layer: DW_LMFF
After feature fusion, we need to match the template feature with the search feature. Traditional Siamese trackers use cross-correlation, which is a local linear operation and may lose global semantic information. Transformer-based matching, on the other hand, excels at global modeling but is weaker in capturing local details. To combine the strengths of both, I propose a novel correlation method named DW_LMFF that concatenates the outputs of a depthwise cross-correlation (DW-Corr) operation and an LMFF-Trans correlation module.
Let the fused template and search features be \(\mathbf{F}_t\) and \(\mathbf{F}_s\). DW-Corr performs depthwise convolution of the search feature using the template feature as a kernel, resulting in a response map that captures local similarities. LMFF-Trans correlation feeds the pair of features into a cross-attention layer (the first LMFF-Trans block) to compute a global interaction map. The final matching result is formed by concatenating these two representations along the channel dimension:
$$
\text{DW\_LMFF}(\mathbf{F}_t, \mathbf{F}_s) = \text{Concat}\big( \text{DW-Corr}(\mathbf{F}_t, \mathbf{F}_s), \text{LMFF}(\mathbf{F}_t, \mathbf{F}_s) \big).
$$
This hybrid matching strategy allows the model to exploit both local details and global context, leading to more precise target localization.
2.4 Prediction Head and Loss Function
The prediction head consists of two branches: a classification branch (CLS) and a regression branch (REG). The classification branch predicts the probability of foreground/background at each spatial location, while the regression branch predicts the distances from each location to the four sides of the bounding box. The classification feature map has size \(w \times h \times 2\), and the regression feature map has size \(w \times h \times 4\).
For training, I use a combined loss consisting of cross-entropy loss \(\mathcal{L}_{cls}\), L1 loss \(\mathcal{L}_{reg}\), and GIoU loss \(\mathcal{L}_{giou}\):
$$
\mathcal{L}_{cls} = -\sum_i y_i \log(\hat{y}_i),
$$
$$
\mathcal{L}_{reg} = \sum_{j \in \{x,y,w,h\}} |y_j – \hat{y}_j|,
$$
$$
\mathcal{L}_{giou} = 1 – \left( \text{IoU} – \frac{|C \setminus (B_{pred} \cup B_{gt})|}{|C|} \right),
$$
where \(B_{pred}\) is the predicted box, \(B_{gt}\) is the ground-truth box, and \(C\) is the smallest enclosing box. Instead of using fixed weights for each loss term, I employ the uncertainty-based weighting method proposed by Kendall et al. The total loss is:
$$
\mathcal{L}_{sum} = \sum_{i=1}^{3} \frac{1}{2\sigma_i^2} \mathcal{L}_i + \ln(1+\sigma_i^2),
$$
where \(\sigma_i\) are learnable parameters that model the homoscedastic uncertainty of each task. This allows the model to automatically balance the importance of classification and regression during training.
3. Experiments and Analysis
3.1 Implementation Details
All experiments are conducted on a workstation with an Intel i9-13900K CPU, an NVIDIA RTX 3090 GPU (24GB), and 32GB RAM, running Windows 11 and PyTorch 1.11.0. The backbone is initialized with weights pre-trained on ImageNet. The initial learning rate for the backbone is \(1 \times 10^{-5}\), while for other modules it is \(1 \times 10^{-4}\). The learnable uncertainty parameters \(\sigma_i\) are initialized to 0.25 and their learning rate is \(1 \times 10^{-4}\). I train the network for 500 epochs with a batch size of 32 and 1875 iterations per epoch. The learning rate is reduced by a factor of 10 after 450 epochs.
I use a combination of LaSOT, TrackingNet, COCO, and GOT-10k datasets for training. The template patch size is 80×80 and the search patch size is 320×320.
3.2 Benchmark Datasets and Metrics
I evaluate SiamLT on three popular tracking benchmarks: UAV123, LaSOT, and GOT-10k. UAV123 contains 123 video sequences captured from a UAV perspective, covering challenges such as fast motion, scale variation, viewpoint change, and occlusion. LaSOT is designed for long-term tracking and emphasizes re-detection after target disappearance. GOT-10k uses a strict class-split protocol to evaluate the generalization ability of the algorithm. The evaluation metrics include AUC (area under the success rate curve), precision (the center location error threshold of 20 pixels), AO (average overlap), and \(SR_{0.5}\) / \(SR_{0.75}\) (success rate at IoU thresholds of 0.5 and 0.75).
3.3 Ablation Studies
To verify the effectiveness of each component in SiamLT, I perform ablation experiments on the UAV123 dataset. The results are summarized in Table 2. The baseline uses AlexNet as the backbone, no fusion network, and standard DW correlation. I incrementally add the GhostNet backbone, the LMFF-Trans fusion network, and the DW_LMFF correlation layer.
| Backbone | Fusion | Features | N | Corr. | Params (M) | FLOPs (G) | AUC (%) | P (%) | FPS |
|---|---|---|---|---|---|---|---|---|---|
| AlexNet | – | – | – | DW | 3.9 | 6.73 | 50.9 | 72.2 | 149 |
| GhostNet | – | – | – | DW | 0.8 | 0.28 | 52.9 | 75.1 | 156 |
| GhostNet | – | – | – | DW_LMFF | 1.5 | 0.56 | 57.7 | 78.6 | 131 |
| GhostNet | FPN | 1~3 | 2 | DW_LMFF | 7.3 | 2.93 | 61.2 | 81.0 | 79 |
| GhostNet | Transformer | 1~3 | 2 | DW_LMFF | 8.7 | 3.16 | 61.8 | 80.7 | 74 |
| GhostNet | LMFF-Trans | 1~3 | 2 | DW_LMFF | 9.1 | 2.76 | 64.6 | 84.5 | 87 |
| GhostNet | LMFF-Trans | 1~3 | 1 | DW_LMFF | 7.2 | 2.06 | 63.1 | 83.5 | 96 |
| GhostNet | LMFF-Trans | 2 | 2 | DW_LMFF | 9.1 | 2.71 | 62.7 | 82.6 | 89 |
| GhostNet | LMFF-Trans | 1~3 | 2 | DW | 7.0 | 1.94 | 61.6 | 81.4 | 98 |
| GhostNet | LMFF-Trans | 1~3 | 2 | LMFF | 7.5 | 2.12 | 62.3 | 82.4 | 96 |
The following observations can be drawn from Table 2:
- Backbone: Replacing AlexNet with GhostNet reduces parameters from 3.9M to 0.8M and increases AUC by 2.0% (from 50.9% to 52.9%). This confirms that GhostNet is both more efficient and more effective for feature extraction.
- Multi-scale fusion: Adding an LMFF-Trans fusion network improves AUC by 6.9% compared with no fusion (from 52.9% to 64.6% with the full model). FPN only improves by 3.5%, while a standard Vision Transformer encoder improves by 4.1%. The proposed LMFF-Trans achieves the best accuracy with fewer FLOPs than the standard Transformer.
- Number of Fusion Blocks: Increasing from one to two Fusion Blocks improves AUC by 1.5%, showing that deeper fusion leads to better feature representation.
- Feature selection: Fusing only a single feature \(F_2\) yields lower AUC (62.7%) than fusing \(F_1, F_2, F_3\) (64.6%). Multi-scale features are beneficial for handling scale variations.
- Correlation method: DW_LMFF improves AUC by 3.0% over DW-only and 2.3% over LMFF-only. This validates the complementarity of local and global matching.
3.4 Comparison with State-of-the-Art Trackers on UAV123
I compare SiamLT with several representative trackers, including Transformer-based trackers (SparseTT, ARTrack, MixFormer), Siamese trackers (SiamFC, SiamCAR, SiamBAN), and UAV-specific trackers (HiFT, SiamAPN++, TCTrack). Table 3 lists the model size and computational complexity.
| Category | Algorithm | Params (M) | FLOPs (G) |
|---|---|---|---|
| Transformer | SparseTT | 46.3 | 9.2 |
| ARTrack | 173.1 | 37.2 | |
| MixFormer | 189.9 | 113.0 | |
| Siamese | SiamFC | 2.3 | 3.2 |
| HiFT | 11.1 | 6.5 | |
| SiamAPN++ | 15.4 | 7.6 | |
| TCTrack | 10.4 | 4.5 | |
| SiamCAR | 51.4 | 59.3 | |
| SiamBAN | 53.9 | 59.6 | |
| Ours | SiamLT | 9.1 | 2.8 |
Figure (success/precision curves) is not reproduced here, but the numeric results are reported. On UAV123, SiamLT achieves an AUC of 64.6% and a precision of 84.5%. This is significantly higher than the classic Siamese trackers SiamFC (AUC 47.6%) and SiamBAN (AUC 61.3%), and also higher than the UAV-specific trackers TCTrack (AUC 58.6%) and HiFT (AUC 57.1%). Although Transformer-based trackers like MixFormer reach higher accuracy (AUC 68.4%), they require 113 G FLOPs, which is roughly 40 times more than SiamLT. Thus, SiamLT offers a much better efficiency-accuracy trade-off for UAV deployment.
I further evaluate the robustness of different algorithms under 12 challenge attributes defined by UAV123: scale variation (SV), aspect ratio change (ARC), low resolution (LR), fast motion (FM), full occlusion (FOC), partial occlusion (POC), out-of-view (OV), background clutter (BC), illumination variation (IV), viewpoint change (VC), camera motion (CM), and similar objects (SOB). Tables 4 and 5 report the AUC and precision values for all attributes.
| Algorithm | SV | ARC | LR | FM | FOC | POC | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| AUC | P | AUC | P | AUC | P | AUC | P | AUC | P | AUC | P | |
| SparseTT | 68.2 | 87.2 | 67.2 | 86.7 | 54.1 | 77.0 | 64.9 | 83.7 | 50.0 | 74.2 | 62.5 | 83.6 |
| ARTrack | 67.1 | 87.7 | 66.6 | 87.4 | 53.4 | 78.7 | 66.1 | 86.9 | 50.2 | 75.5 | 63.2 | 85.6 |
| MixFormer | 68.4 | 89.8 | 69.3 | 91.2 | 54.2 | 80.3 | 67.1 | 88.7 | 52.6 | 78.8 | 64.7 | 87.8 |
| SiamFC | 47.6 | 69.3 | 43.2 | 65.8 | 35.4 | 60.8 | 41.5 | 63.6 | 29.7 | 55.4 | 41.7 | 63.1 |
| HiFT | 57.1 | 76.8 | 53.7 | 73.3 | 42.8 | 65.5 | 55.4 | 77.8 | 35.8 | 58.6 | 48.8 | 68.4 |
| SiamAPN++ | 55.4 | 73.6 | 52.9 | 71.2 | 41.5 | 63.3 | 55.8 | 75.2 | 33.4 | 56.1 | 47.6 | 65.8 |
| TCTrack | 58.6 | 77.8 | 56.6 | 75.3 | 43.8 | 67.9 | 55.3 | 75.7 | 39.1 | 62.3 | 51.8 | 71.6 |
| SiamCAR | 60.5 | 79.1 | 58.0 | 75.9 | 46.5 | 69.3 | 54.9 | 74.2 | 41.9 | 66.0 | 53.3 | 72.4 |
| SiamBAN | 61.3 | 81.3 | 59.1 | 79.6 | 47.2 | 71.9 | 59.3 | 80.5 | 41.8 | 67.1 | 55.0 | 76.5 |
| SiamLT | 62.7 | 82.6 | 62.8 | 83.5 | 50.9 | 75.3 | 57.0 | 76.8 | 49.0 | 75.5 | 58.2 | 79.2 |
| Algorithm | OV | BC | IV | VC | CM | SOB | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| AUC | P | AUC | P | AUC | P | AUC | P | AUC | P | AUC | P | |
| SparseTT | 67.8 | 87.3 | 46.0 | 66.0 | 62.6 | 82.5 | 71.8 | 89.7 | 70.4 | 90.2 | 66.0 | 87.0 |
| ARTrack | 68.0 | 87.5 | 48.9 | 71.4 | 64.2 | 86.2 | 71.2 | 90.9 | 70.7 | 92.6 | 64.8 | 88.5 |
| MixFormer | 67.3 | 87.7 | 53.6 | 77.8 | 65.4 | 88.4 | 72.6 | 92.8 | 72.4 | 95.0 | 67.8 | 92.1 |
| SiamFC | 45.7 | 67.9 | 30.2 | 50.3 | 39.0 | 58.8 | 46.5 | 66.4 | 50.6 | 72.8 | 47.3 | 71.2 |
| HiFT | 52.2 | 70.0 | 39.2 | 59.4 | 50.2 | 70.0 | 58.8 | 76.4 | 60.0 | 79.9 | 51.4 | 71.3 |
| SiamAPN++ | 53.9 | 71.3 | 38.7 | 58.4 | 51.6 | 70.8 | 59.2 | 76.1 | 58.9 | 77.3 | 48.3 | 66.4 |
| TCTrack | 57.5 | 75.2 | 39.7 | 59.1 | 51.8 | 71.0 | 61.6 | 77.1 | 60.5 | 79.7 | 53.1 | 74.1 |
| SiamCAR | 56.4 | 73.5 | 45.8 | 65.9 | 56.6 | 74.8 | 64.6 | 80.7 | 61.2 | 79.7 | 56.3 | 75.4 |
| SiamBAN | 58.9 | 78.9 | 43.1 | 64.5 | 56.5 | 76.6 | 63.9 | 82.4 | 63.9 | 84.8 | 56.6 | 77.7 |
| SiamLT | 62.3 | 82.2 | 51.8 | 75.2 | 56.2 | 76.0 | 65.9 | 84.3 | 65.9 | 86.0 | 60.3 | 81.3 |
From the tables, SiamLT attains outstanding performance on low-resolution, scale variation, out-of-view, and background clutter attributes, exceeding all classic Siamese trackers and UAV-specific trackers. For full occlusion, SiamLT achieves an AUC of 49.0%, which is close to the much heavier MixFormer (52.6%) and well above TCTrack (39.1%). This demonstrates the strong anti-interference capability of the proposed algorithm under challenging UAV conditions.
3.5 Results on LaSOT and GOT-10k
On the long-term tracking dataset LaSOT, SiamLT achieves an AUC of 56.8% and a precision of 56.7%. It outperforms other lightweight Siamese trackers such as SiamGAT (AUC 53.9%), SiamRN (52.7%), and TCTrack (45.6%). The success and precision curves are not shown here, but the numeric comparison confirms the robustness of SiamLT for long-term tracking scenarios.
On GOT-10k, the evaluation results are presented in Table 6. SiamLT achieves an AO of 59.9%, \(SR_{0.5}\) of 69.8%, and \(SR_{0.75}\) of 50.0%. While MixFormer obtains a higher AO (75.6%), its FLOPs are 113 G, making it impractical for embedded UAV platforms. In contrast, SiamLT runs at 36.3 FPS on an Intel i9-13900K CPU and only requires 2.8 G FLOPs, demonstrating an excellent balance between efficiency and accuracy.
| Algorithm | AO (%) | SR\(_{0.5}\) (%) | SR\(_{0.75}\) (%) | FPS (CPU) | FLOPs (G) |
|---|---|---|---|---|---|
| SiamFC | 34.8 | 35.3 | 9.8 | 9.8 | 9.2 |
| SiamBAN | 54.7 | 64.9 | 40.6 | 1.0 | 59.6 |
| HiFT | 49.6 | 58.8 | 27.5 | 5.7 | 6.5 |
| SiamAPN++ | 46.7 | 53.5 | 26.4 | 9.3 | 7.6 |
| TCTrack | 48.2 | 55.6 | 31.0 | 11.5 | 4.5 |
| MixFormer | 75.6 | 85.7 | 72.8 | 0.3 | 113.0 |
| SiamLT | 59.9 | 69.8 | 50.0 | 36.3 | 2.8 |
3.6 Qualitative Analysis
Several representative UAV sequences are selected for qualitative evaluation: bird1, group2, wakeboard6, boat8, and bike2. The tracking screenshots are not reproduced in this article due to formatting constraints, but the observations are as follows.
- In bird1, the target is a small bird viewed from a high altitude with low resolution. The bird flies out of the frame and later re-enters. Only SiamLT is able to re-locate the target after it reappears, benefiting from the shallow feature information preserved by LMFF-Trans.
- In group2, the target is a person who is fully occluded by a building. SiamLT recovers the target after occlusion, while most other trackers lose it permanently.
- In wakeboard6, the target is a person with a very small size, and the camera rotates rapidly causing severe viewpoint change. SiamLT maintains stable tracking without the jitter observed in other methods.
- In boat8, the target is a boat moving quickly toward the camera, causing rapid scale and aspect ratio changes. SiamLT correctly predicts the bounding box size, while other trackers have biased estimates.
- In bike2, the target is a small cyclist that overlaps with a similar object. Only SiamLT and TCTrack avoid confusing the distractor with the target, demonstrating good discrimination ability.
4. Edge Deployment of SiamLT
4.1 CPU Deployment
To evaluate the practicality of SiamLT on resource-constrained devices, I first test its inference speed on several CPUs without a dedicated GPU. Table 7 lists the CPU models used in the experiment.
| Model | Base frequency | Cores | Threads |
|---|---|---|---|
| Intel i9-13900 | 3.00 GHz | 24 | 32 |
| Intel i7-12700 | 2.40 GHz | 14 | 20 |
| Intel i5-9300 | 2.40 GHz | 4 | 8 |
A real-world sequence captured from a UAV is used for testing, where the target is a pedestrian that is temporarily occluded by obstacles. The on-device frame rates are shown in the original figure. On an Intel i9, SiamLT runs at an average of 52 FPS; on an Intel i7, it reaches 36 FPS; even on an older Intel i5, it maintains 23 FPS. In contrast, MixFormerV2 and SiamBAN run at only 7 FPS and 5 FPS on the i9 CPU, which is far below the real-time requirement. These results confirm that SiamLT is lightweight enough for CPU-only execution.
4.2 NPU Platforms and Quantization
For UAV platforms, NPU (Neural Processing Unit) is a more energy-efficient option than GPU. In this work, I deploy SiamLT on two popular edge chips: the Rockchip RK3588 and the Huawei Ascend 310. The RK3588 offers 6 TOPS computing power, while the Ascend 310 provides 8 TOPS. Both support INT8 and FP16 precision. To fully exploit their parallel computing capability, the model must be quantized from FP32 to INT8.
The quantization process can be summarized as follows. Given a floating-point value \(X\), a scale factor \(S\), and a zero-point offset \(Z\), the integer representation \(Q\) is computed by:
$$
Q = \text{clip}\left( \text{round}\left( \frac{X}{S} + Z \right), -2^{b-1}, 2^{b-1}-1 \right),
$$
where \(b=8\) for INT8 quantization. The dequantized value is \(X’ = S(Q-Z)\). The error between \(X\) and \(X’\) arises from the rounding and clipping operations.
Because the weight distribution of different channels may be asymmetric, I adopt asymmetric quantization with a non-zero offset \(Z\). I also choose a per-channel quantization granularity, where each channel has its own scale and offset, to better preserve the dynamic range of the weights.
To determine the optimal quantization parameters, I compare three calibration algorithms: Normal (based on min/max), KL divergence, and MMSE (minimum mean squared error). The experiments are conducted on both the template branch and the search branch separately, referred to as separated quantization. This avoids redundant re-computation of the template features in every frame.
| Algorithm | Template branch | Search branch | ||
|---|---|---|---|---|
| COS | EUC | COS | EUC | |
| Normal | 0.9857 | 125.31 | 0.9953 | 0.6462 |
| KL | 0.9865 | 121.94 | 0.9952 | 0.7108 |
| MMSE | 0.9929 | 88.80 | 0.9968 | 0.5518 |
MMSE yields the highest cosine similarity and the lowest Euclidean distance in both branches, indicating the smallest quantization error. Therefore, I use MMSE quantization for the final deployed model.
Table 9 and Table 10 show the detailed operator statistics of the quantized model on the RK3588 NPU. The template branch has 328 operator invocations with a total NPU time of 10593 microseconds. The search branch, which includes the correlation and head layers, has 369 operators and takes 49147 microseconds on the NPU.
| Operator | Count | CPU (us) | NPU (us) | Total (us) | Ratio (%) |
|---|---|---|---|---|---|
| Conv | 79 | 0 | 2298 | 2298 | 21.67% |
| exNorm | 38 | 0 | 1908 | 1908 | 17.99% |
| ConvRelu | 40 | 0 | 1209 | 1209 | 11.40% |
| Concat | 36 | 0 | 1105 | 1105 | 10.42% |
| exSDPAttention | 8 | 0 | 916 | 916 | 8.64% |
| ConvAdd | 21 | 0 | 760 | 760 | 7.17% |
| ConvExGelu | 8 | 0 | 390 | 390 | 3.68% |
| Reshape | 38 | 0 | 344 | 344 | 3.24% |
| Mul | 14 | 0 | 304 | 304 | 2.87% |
| AveragePool | 10 | 0 | 293 | 293 | 2.76% |
| Split | 8 | 0 | 281 | 281 | 2.65% |
| ConvClip | 7 | 0 | 271 | 271 | 2.56% |
| exGelu | 8 | 0 | 264 | 264 | 2.49% |
| Add | 11 | 0 | 250 | 250 | 2.36% |
| OutputOperator | 1 | 9 | 0 | 9 | 0.08% |
| InputOperator | 1 | 4 | 0 | 4 | 0.04% |
| Total | 328 | 13 | 10593 | 10606 | – |
| Operator | Count | CPU (us) | NPU (us) | Total (us) | Ratio (%) |
|---|---|---|---|---|---|
| exSDPAttention | 9 | 0 | 13875 | 13875 | 28.17% |
| exNorm | 43 | 0 | 11276 | 11276 | 22.89% |
| Conv | 91 | 0 | 5975 | 5975 | 12.13% |
| ConvRelu | 45 | 0 | 4639 | 4639 | 9.42% |
| Concat | 38 | 0 | 4022 | 4022 | 8.17% |
| ConvAdd | 23 | 0 | 2374 | 2374 | 4.82% |
| ConvExGelu | 9 | 0 | 2234 | 2234 | 4.54% |
| Reshape | 43 | 92 | 1086 | 1178 | 2.39% |
| AveragePool | 11 | 0 | 867 | 867 | 1.76% |
| Mul | 14 | 0 | 592 | 592 | 1.20% |
| Transpose | 3 | 0 | 527 | 527 | 1.07% |
| Add | 11 | 0 | 518 | 518 | 1.05% |
| Split | 9 | 0 | 467 | 467 | 0.95% |
| exGelu | 9 | 0 | 425 | 425 | 0.86% |
| ConvClip | 7 | 0 | 270 | 270 | 0.55% |
| OutputOperator | 2 | 13 | 0 | 13 | 0.03% |
| InputOperator | 2 | 5 | 0 | 5 | 0.01% |
| Total | 369 | 110 | 49147 | 49257 | – |
The statistics show that the NPU carries more than 99% of the computation. The attention operator (exSDPAttention) dominates in the search branch, while convolution dominates in the template branch. These findings indicate opportunities for further optimization by fusing or pruning specific operators.
4.3 Quantization Accuracy and Inference Speed
Table 11 compares the model size, accuracy on GOT-10k, and inference latency under different formats and hardware platforms. The original PyTorch FP32 model achieves an AO of 59.9% on an RTX 3090 GPU with 11.49 ms latency. After conversion to ONNX, the model size drops from 104.9 MB to 59.8 MB with negligible accuracy loss. However, the inference on an RK3588 CPU takes 159.49 ms, which is too slow for real-time tracking.
After INT8 quantization into RKNN format, the model size is further reduced to 23.9 MB, and the latency on the RK3588 NPU decreases to 54.70 ms (about 18 FPS). The AO remains 58.5%, with \(SR_{0.5}\) and \(SR_{0.75}\) equal to 68.8% and 48.1%, respectively. This demonstrates that quantization effectively accelerates the inference while preserving acceptable accuracy.
| Model format | Device | Weight size (MB) | AO (%) | SR\(_{0.5}\) (%) | SR\(_{0.75}\) (%) | Latency (ms) |
|---|---|---|---|---|---|---|
| PyTorch (FP32) | RTX 3090 GPU | 104.9 | 59.9 | 69.8 | 50.0 | 11.49 |
| ONNX (FP32) | RK3588 CPU | 59.8 | 59.7 | 70.0 | 50.2 | 159.49 |
| RKNN (INT8) | RK3588 NPU | 23.9 | 58.5 | 68.8 | 48.1 | 54.70 |
4.4 Frame Rate Comparison on Edge Devices
I also deploy the quantized model on the Ascend 310 platform. Figure (frame rate comparison) shows the inference speed on both RK3588 and Ascend 310 for different configurations: the default SiamLT with two Fusion Blocks, the version with one Fusion Block, and the version with a standard Vision Transformer encoder instead of LMFF-Trans. The measured frame rates are summarized in Table 12.
| Configuration | RK3588 (6 TOPS) | Ascend 310 (8 TOPS) |
|---|---|---|
| SiamLT (2 Fusion Blocks) | 20 | 28 |
| SiamLT (1 Fusion Block) | 27 | 33 |
| Standard Transformer | 8 | 18 |
The results show that the Ascend 310, having higher NPU throughput, achieves faster inference. Reducing the number of Fusion Blocks improves the speed to 27/33 FPS, demonstrating the flexibility of the design. More importantly, replacing LMFF-Trans with a standard Transformer drops the frame rate to 8 FPS on RK3588. This verifies the computational efficiency of the proposed feature compression mechanism.
5. Quadrotor UAV Platform and System Implementation
5.1 Quadrotor Flight Principle
I built a quadrotor UAV platform with an X-frame configuration. The four rotors are labeled \(M_1, M_2, M_3, M_4\). The two rotors on the same diagonal rotate in the same direction, and the propellers are chosen as a pair of counter-rotating blades to cancel the reactive torque. By adjusting the speed of each rotor, the UAV can achieve vertical take-off/landing, pitch, roll, and yaw movements.
- Vertical motion: Increasing the speed of all four rotors simultaneously produces more lift than the gravitational force, causing the drone to ascend. Decreasing them causes descent. When lift equals gravity, the drone hovers.
- Pitch: Increasing the speed of the front rotors (\(M_1\) and \(M_4\)) and decreasing the rear rotors (\(M_2\) and \(M_3\)) tilts the body forward, generating forward motion. The opposite produces backward motion.
- Roll: Increasing the speed of the right rotors (\(M_3\) and \(M_4\)) and decreasing the left rotors (\(M_1\) and \(M_2\)) generates rightward motion, and the opposite yields leftward motion.
- Yaw: Increasing the speed of one diagonal pair (\(M_1\) and \(M_3\)) and decreasing the other diagonal pair (\(M_2\) and \(M_4\)) produces a reactive torque difference that rotates the body around the vertical axis.
5.2 Serial Cascade PID Controller
To stabilize the flight attitude, I design a cascade PID controller consisting of an outer loop and an inner loop. The outer loop regulates the attitude angle and generates the desired angular velocity. The inner loop controls the angular velocity and outputs the motor command. The control law is as follows:
$$
u(t) = K_p e(t) + K_i \int e(t) dt + K_d \frac{de(t)}{dt}.
$$
For the outer loop:
$$
\omega(t) = K_{p,outer} e_{\theta}(t) + K_{i,outer} \int e_{\theta}(t) dt + K_{d,outer} \frac{d e_{\theta}(t)}{dt},
$$
and for the inner loop:
$$
u(t) = K_{p,inner} e_{\omega}(t) + K_{i,inner} \int e_{\omega}(t) dt + K_{d,inner} \frac{d e_{\omega}(t)}{dt}.
$$
This cascade structure allows faster and more accurate attitude tracking, effectively reducing overshoot and oscillation.
5.3 Hardware and Software Design
The developed quadrotor UAV system consists of the following main components:
- Microcontroller unit (MCU): STM32F407 (ARM Cortex-M4) is used as the flight controller. It reads sensor data via IIC and SPI, communicates with the edge computing device via USART, generates PWM signals to drive the electronic speed controllers (ESCs), and stores essential parameters in a W25Q32 flash chip.
- Edge computing device: The Rockchip RK3588 is used for visual processing. It captures camera images and runs the quantized SiamLT model to obtain the target bounding box. The tracking command is then sent to the MCU to control the UAV.
- Attitude sensors: The ICM20602 six-axis IMU (gyroscope and accelerometer) measures angular velocity and acceleration. The SPL06 barometer measures air pressure to estimate altitude.
- Power system: A battery supplies power to both the MCU and the edge computer, with appropriate voltage regulators.
The actual drone built in this project is shown in the original figure. The integration of the lightweight tracking algorithm into the RK3588 platform enables real-time onboard tracking.
5.4 Onboard Tracking Experiments
I performed real-world flight tests to validate the complete system. Two scenarios are considered: a normal scene with a walking pedestrian and a complex scene with a vehicle moving through a cluttered background.
In the normal scene, the target pedestrian is partially occluded by trees at video frames 44–65 and 156–206. The proposed algorithm accurately estimates the target scale and continues tracking after the occlusion. The GPS-like view shows that the system maintains a stable tracking performance at about 20 FPS.
In the complex scene, the target is a vehicle that turns at a corner, causing a drastic aspect ratio change and a switch from a side view to a rear view. The background contains many distracting objects. Despite these challenges, SiamLT keeps the target locked throughout the sequence. The tracking results from the onboard camera confirm that the system exhibits high accuracy and strong anti-interference ability.
These experiments verify that the proposed UAV target tracking system can operate reliably in real-world conditions, meeting the requirements of practical applications.
6. Conclusion
In this work, I have presented a comprehensive research study on deep-learning-based target tracking systems for quadrotor unmanned aerial vehicles. The main contributions are threefold. First, I proposed a lightweight yet accurate tracking algorithm SiamLT, which employs a GhostNet backbone to extract multi-scale features and an improved LMFF-Trans structure to fuse them effectively. The proposed DW_LMFF correlation layer combines local and global matching information, leading to precise target localization. Experimental results on UAV123, LaSOT, and GOT-10k demonstrate that SiamLT achieves state-of-the-art accuracy among lightweight trackers with only 2.8 G FLOPs and 9.1 M parameters.
Second, I investigated the edge deployment of SiamLT on CPU and NPU platforms. Through asymmetric per-channel quantization with the MMSE calibration algorithm, the model size was reduced from 104.9 MB to 23.9 MB, and the inference latency on the RK3588 NPU dropped to 54.70 ms. The quantized model runs at 28 FPS on the Ascend 310 and 20 FPS on the RK3588, making it suitable for real-time UAV applications.
Third, I designed and implemented a complete quadrotor UAV platform with a cascade PID controller and an onboard RK3588 computer. Real flight experiments confirmed that the system can track both pedestrians and vehicles in normal and complex scenes, maintaining stable performance under occlusion, scale changes, viewpoint changes, and background clutter. Future work will focus on further operator-level optimization to improve NPU utilization, as well as the integration of multi-modal sensors to enable autonomous navigation and obstacle avoidance.