
We present a novel deep reinforcement learning framework, termed the Gated Aggregation Network based Deep Reinforcement Learning Method (GNDRL), to address the multi-UAV dynamic path optimization problem in urban logistics delivery. Our approach is deeply rooted in drone technology, leveraging the advances in deep learning and attention mechanisms to overcome the inherent limitations of battery endurance and cooperative scheduling in multi-UAV systems. The core innovation lies in a dual-stage architecture: state enhancement via a gated attention mechanism that dynamically fuses heterogeneous node features, and decision generation that incorporates real-time energy states to achieve efficient path planning. We demonstrate that GNDRL significantly reduces total flight distance while maintaining low computational overhead across various problem scales and node distributions.
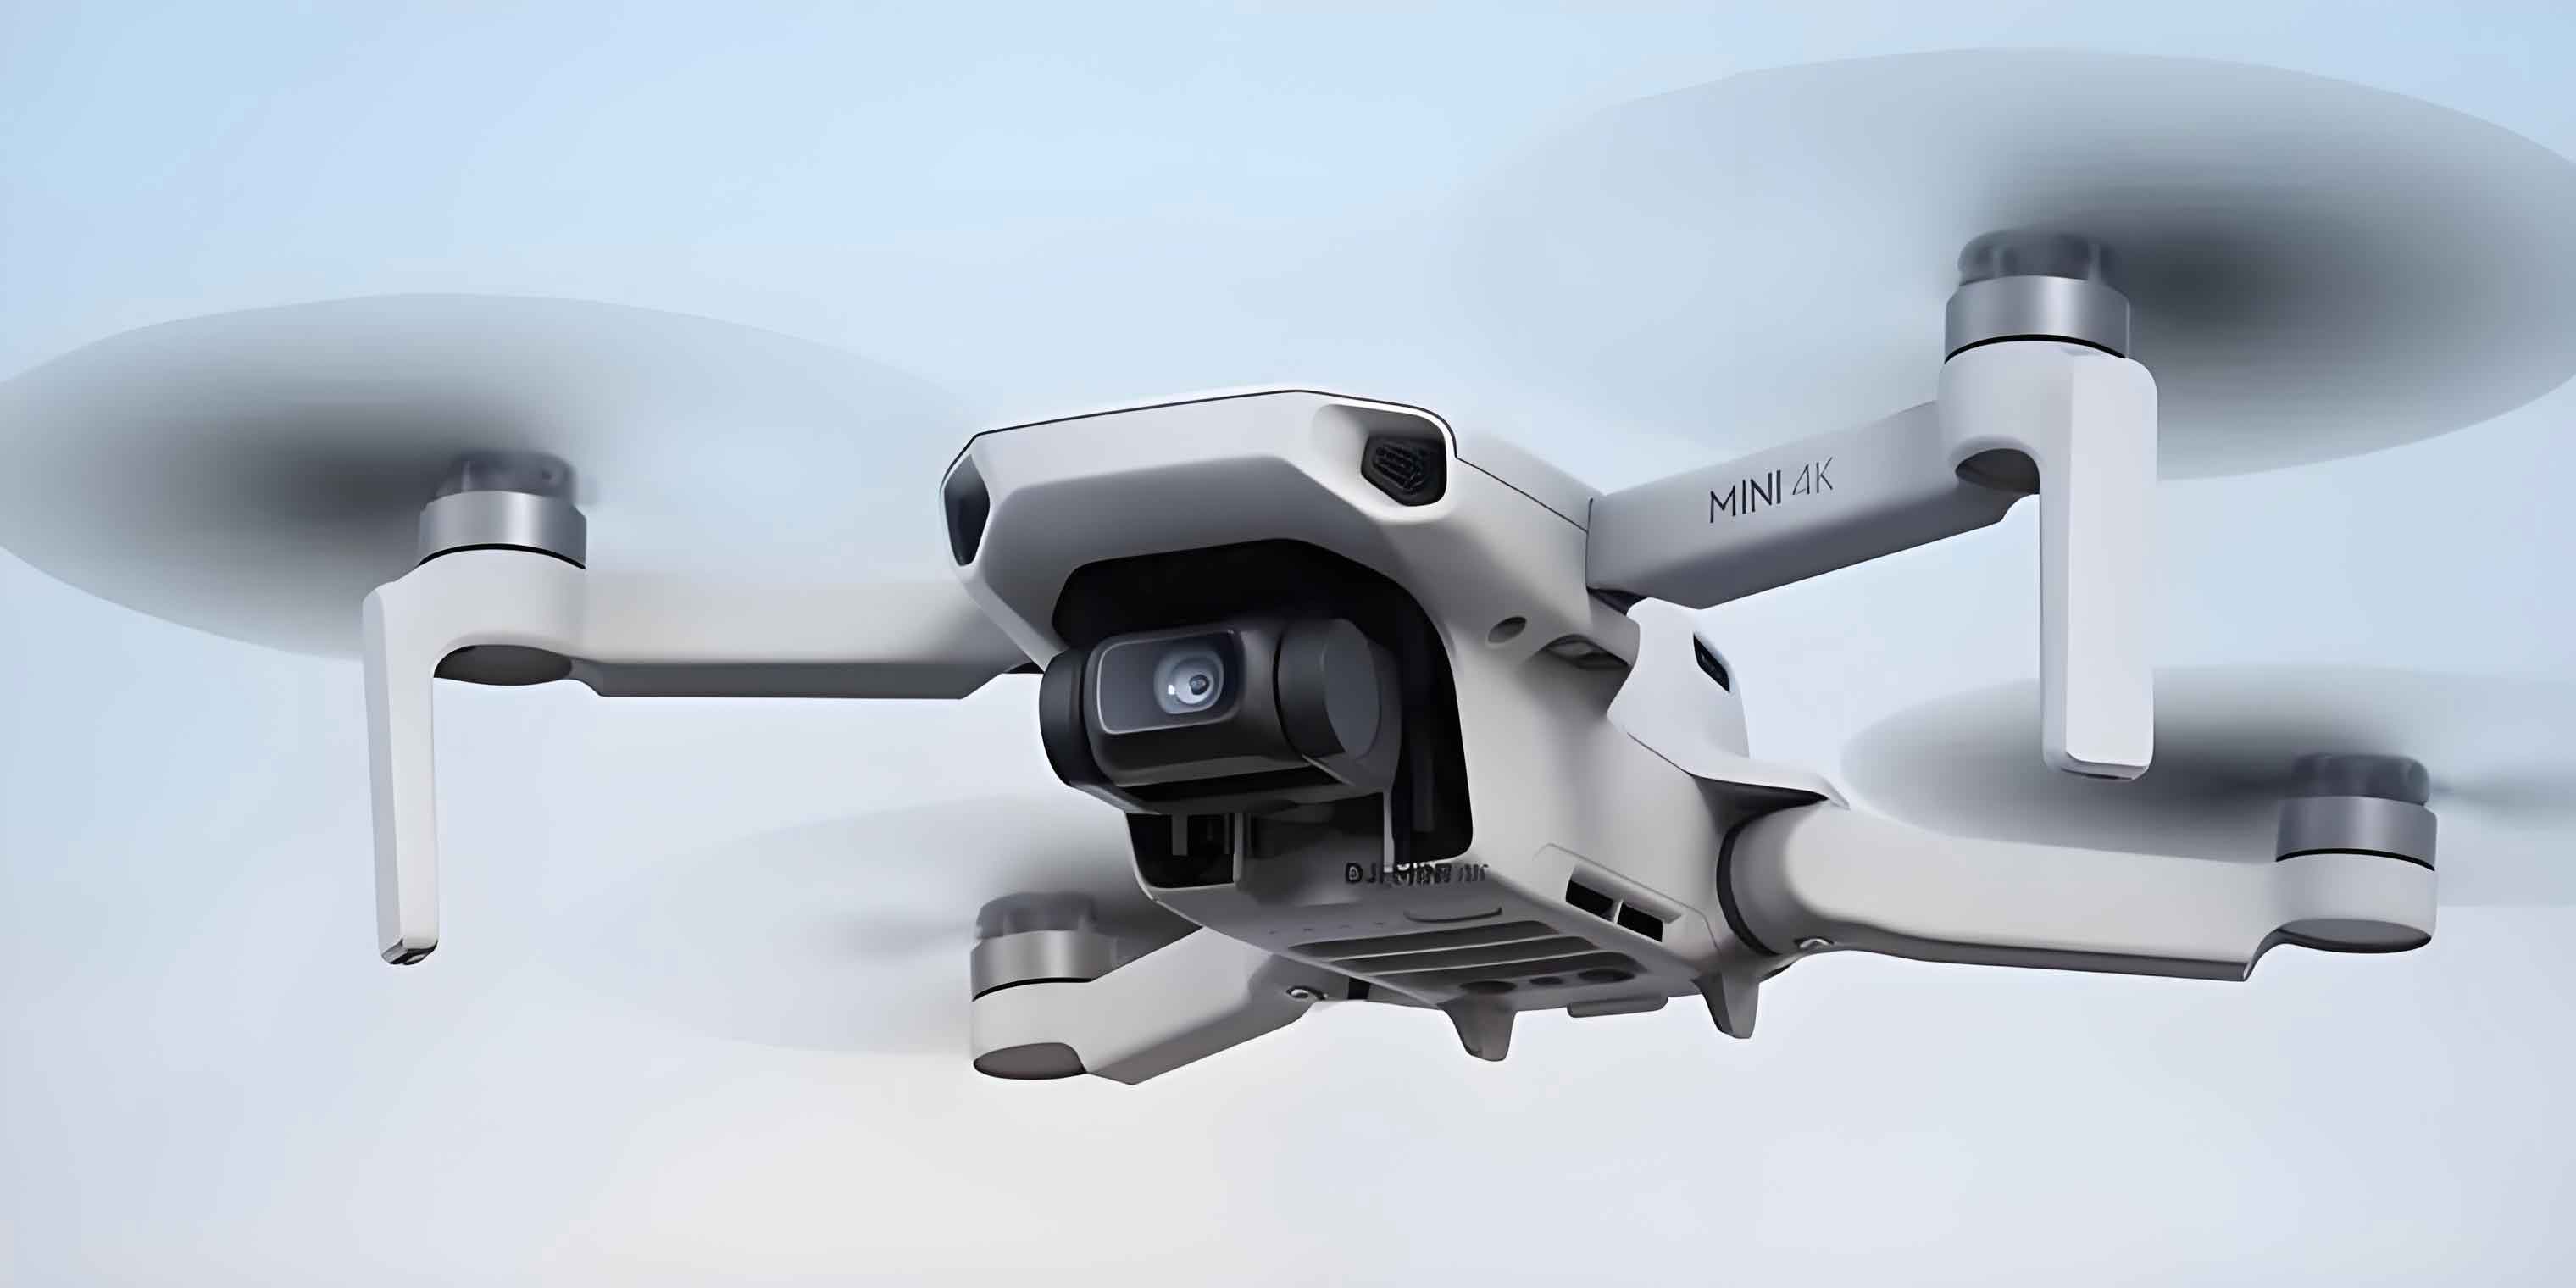
1. Introduction
Drone technology has emerged as a transformative force for urban logistics, offering unparalleled flexibility in three-dimensional airspace. The coordination of multiple drones (multi-UAV) can substantially increase delivery efficiency and reduce operational costs, especially in time-sensitive scenarios such as emergency medical supply deliveries. However, the limited battery capacity imposes strict energy constraints, making multi-UAV routing with en-route charging stations a critical challenge. Existing methods, including exact algorithms and metaheuristics, often suffer from either exponential computational complexity or poor generalization to dynamic environments. Deep reinforcement learning (DRL) has recently shown promise by transforming NP-hard combinatorial problems into sequential decision-making tasks. Yet, most DRL-based solvers treat charging and task execution as two independent stages, leading to suboptimal solutions.
To bridge this gap, we propose GNDRL, a DRL method that jointly optimizes task sequencing and charging decisions within a single framework. Our work is firmly positioned in the field of drone technology, aiming to provide an end-to-end learning paradigm for dynamic path optimization. The main contributions are:
- A dual-stage state enhancement–decision generation architecture that dynamically captures global and local dependencies among heterogeneous nodes (depot, tasks, charging stations).
- A gated fusion attention mechanism that adaptively weights self-attention and cross-attention outputs, improving feature representation for complex graphs.
- Integration of real-time battery states into the decision module to ensure energy-feasible actions.
- Extensive experiments on varied problem sizes and distributions demonstrate superior performance over mainstream DRL baselines and classical metaheuristics.
2. Problem Formulation
We model the multi-UAV dynamic path optimization problem as a variant of the vehicle routing problem with energy constraints. Let \(G=(V,E)\) be a directed graph, where \(V\) consists of a depot (node 0), a set of task nodes \(N\) (size \(n\)), and a set of charging stations \(C\) (size \(z\)). Each node has attributes (type, flag, coordinates). Edge weight \(d_{ij}\) represents the Euclidean distance between nodes \(i\) and \(j\). The objective is to minimize the total travel distance of all drones, subject to constraints on battery capacity, load capacity, and service requirements. We define the following mixed-integer linear programming model.
Sets and indices:
- \(K\): set of drones.
- \(N\): set of task nodes.
- \(C\): set of charging stations, with \(C’_s\) representing the set of virtual copies allowing multiple visits.
- \(V_a = N \cup C’\).
- \(V_0 = \{0\} \cup V_a\), \(V_{n+1} = V_a \cup \{n+1\}\).
Parameters: \(Q_{\text{cap}}\) (max load), \(L_{\text{max}}\) (max flight distance), \(r\) (energy consumption per unit distance), \(e_u, e_d, e_h\) (energy for takeoff, landing, hover), \(q_i\) (demand weight).
Decision variables: \(x_{ij}^k \in \{0,1\}\) indicates if drone \(k\) travels from \(i\) to \(j\); \(y_i^k\) is the remaining battery upon arrival at \(i\); \(u_i^k\) is the visit order; \(l_i^k\) is the remaining load after leaving \(i\).
Objective:
$$
\min \sum_{k\in K}\sum_{i\in V_0}\sum_{j\in V_{n+1}, i\neq j} d_{ij} x_{ij}^k
$$
Constraints:
Each task node is visited exactly once:
$$
\sum_{k\in K}\sum_{j\in V_{n+1}, j\neq i} x_{ij}^k = 1, \quad \forall i \in N
$$
Each charging station visit is optional:
$$
\sum_{k\in K}\sum_{j\in V_{n+1}, j\neq i} x_{ij}^k \le 1, \quad \forall i \in C’
$$
Flow conservation:
$$
\sum_{j\in V_{n+1}, j\neq i} x_{ij}^k – \sum_{j\in V_0, j\neq i} x_{ji}^k = 0, \quad \forall i \in V_a, k\in K
$$
Battery feasibility:
$$
0 < y_j^k \le y_i^k – r d_{ij} – e_h + Q_{\text{max}}(1 – x_{ij}^k), \quad \forall i,j\in N, i\neq j, k\in K
$$
Charging transition constraints:
$$
0 < y_j^k \le y_i^k – r d_{ij} – e_d + Q_{\text{max}}(1 – x_{ij}^k), \quad \forall i\in N, j\in C’
$$
$$
0 < y_i^k < Q_{\text{max}} – r d_{ij} + e_h + e_u, \quad \forall i\in C’, j\in N
$$
Subtour elimination:
$$
u_i^k – u_j^k + 1 \le (n+z)(1 – x_{ij}^k), \quad \forall i,j\in V_a, i\neq j
$$
Load constraints:
$$
l_j^k \ge l_i^k + q_j – Q_{\text{cap}}(1 – x_{ij}^k), \quad 0 \le l_i^k \le Q_{\text{cap}}
$$
Depot start and end:
$$
\sum_{j\in N\cup C’} x_{0j}^k = 1, \quad \sum_{i\in N\cup C’} x_{i,(n+1)}^k = 1, \quad \forall k
$$
3. Markov Decision Process Design
We formulate the construction of a feasible route as a sequential decision process. The state \(s_t\) consists of three components: (i) the partial sequence of visited nodes \(N_t\), (ii) the remaining battery vector \(Q_t\) for each drone, and (iii) the current load vector \(l_t\). The action \(a_t\) is the next task node or charging station that is reachable under the current battery level and load capacity. Transition probability \(P(s_{t+1}|s_t,a_t)=1\) for feasible actions, and 0 otherwise. The reward \(R\) is defined as the negative of total flight distance upon completion of all tasks:
$$
R = -\sum_{k=1}^{|K|} D_k
$$
where \(D_k\) is the total distance flown by drone \(k\) in the constructed solution.
4. GNDRL Architecture
4.1 State Enhancement Module
The encoder processes all nodes (depot, tasks, charging stations) through \(L\) identical gated attention layers. Each layer comprises a gated fusion attention sublayer and a feed-forward network (FFN) with residual connections and batch normalization. The input node features \(\mathbf{h}_i^0\) are obtained by linear projection of the concatenated coordinate and type one-hot vectors into a 128-dimensional space.
Within each layer, we compute self-attention (SA) and cross-attention (CA) outputs:
$$
\text{SA}(\mathbf{h}_i) = \text{MHA}(\mathbf{h}_i; \mathbf{h}_0,\ldots,\mathbf{h}_{n+z})
$$
$$
\text{CA}(\mathbf{h}_i) = \text{MHA}(\mathbf{h}_i; \mathbf{h}_{n+1},\ldots,\mathbf{h}_{n+z})
$$
where \(\text{MHA}\) denotes multi-head attention with 8 heads and head dimension 16. The gating coefficient \(\lambda_i\) is learned dynamically:
$$
\lambda_i = \sigma(\mathbf{W}_g \cdot \text{Concat}(\text{SA}(\mathbf{h}_i), \text{CA}(\mathbf{h}_i)) + \mathbf{b}_g)
$$
Then the fused representation is:
$$
\tilde{\mathbf{h}}_i = \lambda_i \cdot \text{SA}(\mathbf{h}_i) + (1-\lambda_i) \cdot \text{CA}(\mathbf{h}_i)
$$
A gated connection merges the previous layer representation:
$$
\mathbf{h}’_i = \text{BN}\big(g \cdot \mathbf{h}_i^{(l-1)} + (1-g)\cdot \tilde{\mathbf{h}}_i\big)
$$
Finally, the FFN layer applies:
$$
\text{FF}(\mathbf{h}’_i) = \mathbf{W}_2 \cdot \text{GELU}(\mathbf{W}_1 \mathbf{h}’_i + \mathbf{b}_1) + \mathbf{b}_2
$$
$$
\mathbf{h}_i^{(l)} = \text{BN}\big(\mathbf{h}’_i + \text{FF}(\mathbf{h}’_i)\big)
$$
After \(L\) layers, the graph embedding is obtained by mean pooling:
$$
\bar{\mathbf{h}} = \frac{1}{n+z+1}\sum_{i=0}^{n+z}\mathbf{h}_i^{(L)}
$$
4.2 Decision Generation Module
The decoder operates autoregressively. At time step \(t\), the context vector \(\mathbf{h}_t^{\text{con}}\) is formed by concatenating the graph embedding \(\bar{\mathbf{h}}\), the embedding of the current node \(\mathbf{h}_{\pi_{t-1}}^{(L)}\), and the current battery residual \(Q_t\):
$$
\mathbf{h}_t^{\text{con}} = \mathbf{W}_{\text{graph}}\bar{\mathbf{h}} + \mathbf{W}_{\text{con}}\cdot \text{Cat}(\mathbf{h}_{\pi_{t-1}}^{(L)}, Q_t)
$$
Then a multi-head attention layer refines the context:
$$
\mathbf{h}_t^m = \text{MHA}(\mathbf{h}_t^{\text{con}}, \mathbf{h}_0^{(L)},\ldots,\mathbf{h}_{n+z}^{(L)})
$$
A single-head attention computes compatibility scores with each node:
$$
q_t = \mathbf{W}_Q \mathbf{h}_t^m, \quad k_i = \mathbf{W}_K \mathbf{h}_i^{(L)}
$$
$$
p_i = \text{softmax}\left( C \tanh\left( \frac{q_t k_i}{\sqrt{d_k}}\right) \right)
$$
where \(C\) is a clipping parameter (set to 10). Nodes that are already visited, unreachable due to battery, or would make the drone unable to reach any charging station are masked with \(-\infty\). The next node \(\pi_t\) is either greedily selected or sampled from the distribution.
4.3 Training Procedure
We adopt an actor-critic style using a policy network with parameters \(\eta\) and a baseline network with parameters \(\varphi\). For each training batch of size \(b\), we sample problem instances, let the policy network interact to generate solutions, compute cumulative rewards, and compute the baseline reward via greedy decoding. The policy gradient update is:
$$
d\eta = \frac{1}{b}\sum_{\lambda=1}^{b} \big(R(\lambda) – u_{\varphi}(\lambda)\big) \nabla_\eta \log p_\eta(\pi_\lambda)
$$
$$
\eta_{t+1} = \eta_t + \nu d\eta
$$
The baseline parameters are updated by copying the policy parameters only when a statistical test (paired t-test) confirms significant improvement, ensuring training stability.
5. Experimental Setup
We generate three problem sizes: D20 (20 tasks + 2 charging stations), D50 (50 tasks + 10 charging stations), and D100 (100 tasks + 20 charging stations). All node coordinates are uniformly sampled from \([0,1]^2\), except charging stations which are drawn from the discrete set \(\{0,0.25,0.5,0.75,1\}^2\). Battery capacity is set to \(L_{\text{max}}=3\), unit energy consumption \(r=1\). We set \(e_u=e_d=e_h=0\) for simplicity (focusing on flight distance optimization).
Hyperparameters: 3 encoder layers, 8 attention heads, hidden dimension 128, batch size 256, learning rate \(1e-4\) decayed by 0.995 per epoch, 100 training epochs. All methods are implemented in PyTorch and trained on an Nvidia RTX 4070 Ti Super.
6. Results and Discussion
6.1 Training Convergence
We compare training curves of GNDRL, AM (Attention Model), and HADRL (Heterogeneous Attention based DRL) for D20, D50, and D100.
Table 1: Final objective values (after 100 epochs) for different methods.
| Method | D20 | D50 | D100 |
|---|---|---|---|
| AM | 7.45 | 9.16 | 12.70 |
| HADRL | 6.74 | 8.52 | 12.66 |
| GNDRL | 6.34 | 8.49 | 11.20 |
GNDRL achieves the lowest objective across all scales, with improvements of 8.9%–17.6% over AM. The gap widens as problem size increases, indicating superior scalability.
6.2 Ablation Study
We evaluate the contributions of the gated fusion attention (GFA) and gated connection (GC) modules. Results on D50:
Table 2: Ablation results (average over 50 random instances).
| Configuration | Objective | Time (s) |
|---|---|---|
| Basic | 8.96 | 0.16 |
| +GFA | 8.72 | 0.17 |
| +GC | 8.55 | 0.16 |
| +Both (GNDRL) | 8.49 | 0.17 |
Both modules contribute positively, with the combined effect yielding the best performance.
6.3 Comparison with Baselines
We compare GNDRL with classical metaheuristics (VNS, SA, GA, PSO) and DRL baselines (AM, HADRL) under both greedy (GS) and sampling strategies. Results are reported in Table 3.
Table 3: Performance comparison over 100 test instances for each size.
| Method | D20 | D50 | D100 | ||||||
|---|---|---|---|---|---|---|---|---|---|
| Obj | Gap | Time(s) | Obj | Gap | Time(s) | Obj | Gap | Time(s) | |
| VNS | 8.07 | 21.4% | 0.16 | 20.08 | 57.7% | 1.16 | 41.52 | 73.0% | 4.99 |
| SA | 12.15 | 47.8% | 0.01 | 32.14 | 73.5% | 0.01 | 61.88 | 81.9% | 0.04 |
| GA | 7.55 | 16.0% | 8.29 | 20.60 | 62.4% | 56.91 | 39.36 | 71.5% | 254.0 |
| PSO | 8.30 | 23.6% | 0.99 | 22.57 | 62.3% | 1.20 | 46.31 | 75.8% | 4.67 |
| AM(GS) | 7.62 | 16.7% | 0.13 | 9.82 | 13.5% | 0.14 | 14.65 | 23.5% | 0.26 |
| AM | 7.45 | 14.8% | 0.13 | 9.16 | 7.3% | 0.16 | 12.70 | 11.8% | 0.30 |
| HADRL(GS) | 6.84 | 7.3% | 0.14 | 8.82 | 3.7% | 0.18 | 12.88 | 13.0% | 0.26 |
| HADRL | 6.74 | 5.9% | 0.15 | 8.52 | 3.0% | 0.16 | 12.66 | 11.5% | 0.27 |
| GNDRL(GS) | 6.77 | 6.3% | 0.14 | 8.65 | 1.8% | 0.16 | 11.47 | 2.3% | 0.25 |
| GNDRL | 6.34 | 0% | 0.15 | 8.49 | 0% | 0.17 | 11.20 | 0% | 0.27 |
GNDRL consistently outperforms all other methods, especially in larger instances. The greedy version (GS) also achieves competitive results, confirming the model’s robustness.
6.4 Generalization to Larger Scales
We test the D100-trained model on D150 (150 tasks +30 charging stations) and D200 (200 tasks +35 stations). Results are shown in Table 4.
Table 4: Large-scale generalization results.
| Method | D150 Obj | Time(s) | D200 Obj | Time(s) |
|---|---|---|---|---|
| VNS | 62.65 | 11.8 | 84.14 | 20.8 |
| SA | 88.66 | 0.09 | 101.62 | 0.12 |
| GA | 63.86 | 606 | 82.13 | 1043 |
| PSO | 76.39 | 7.36 | 99.39 | 10.8 |
| AM | 18.89 | 0.38 | 22.75 | 0.49 |
| HADRL | 19.10 | 0.41 | 18.60 | 0.49 |
| GNDRL | 15.28 | 0.39 | 18.40 | 0.49 |
GNDRL maintains its advantage, demonstrating remarkable generalization ability without retraining.
6.5 Sensitivity to Battery Capacity and Charging Station Density
We evaluate GNDRL under reduced battery capacity (90% of original) on D20 and D50. Table 5 summarizes.
Table 5: Performance under 90% battery capacity.
| Instance | Objective (100% cap) | Objective (90% cap) | Time (s) |
|---|---|---|---|
| D20 | 6.34 | 6.55 | 0.21 |
| D50 | 8.49 | 8.60 | 0.23 |
The performance degradation is less than 3%, indicating strong robustness to energy constraints.
We also test different charging station densities on D50 by varying the number of stations from 4 to 8. The objective values are stable (around 8.4–8.6), confirming that GNDRL can adapt to sparse charging infrastructure.
6.6 Performance under Non‑uniform Distributions
We train on uniform distributions and test on Gaussian and Rayleigh distributions with varying spreads. Tables 6 and 7 report quantitative results.
Table 6: Performance on Gaussian-distributed instances.
| Method | G20(0.3) | G50(0.3) | G100(0.3) | G20(0.6) | G50(0.6) | G100(0.6) | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Obj | Time | Obj | Time | Obj | Time | Obj | Time | Obj | Time | Obj | Time | |
| AM | 7.17 | 0.12 | 9.86 | 0.24 | 16.36 | 0.46 | 8.44 | 0.13 | 10.21 | 0.23 | 16.40 | 0.40 |
| HADRL | 6.61 | 0.12 | 8.57 | 0.22 | 14.11 | 0.36 | 7.46 | 0.17 | 9.12 | 0.23 | 14.58 | 0.39 |
| GNDRL | 6.55 | 0.14 | 8.39 | 0.13 | 12.11 | 0.29 | 7.45 | 0.29 | 8.25 | 0.14 | 14.01 | 0.30 |
Table 7: Performance on Rayleigh-distributed instances.
| Method | R20(0.25) | R50(0.25) | R100(0.25) | R20(0.4) | R50(0.4) | R100(0.4) | ||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Obj | Time | Obj | Time | Obj | Time | Obj | Time | Obj | Time | Obj | Time | |
| AM | 15.52 | 0.11 | 24.40 | 0.24 | 43.90 | 0.38 | 6.01 | 0.13 | 8.19 | 0.18 | 12.96 | 0.30 |
| HADRL | 5.12 | 0.21 | 7.93 | 0.34 | 11.42 | 0.61 | 7.19 | 0.22 | 8.63 | 0.37 | 11.63 | 0.55 |
| GNDRL | 4.51 | 0.24 | 5.85 | 0.38 | 8.48 | 0.67 | 5.67 | 0.22 | 6.58 | 0.38 | 11.50 | 0.65 |
GNDRL achieves the best objective in all settings, proving its ability to handle non‑uniform data distributions commonly encountered in real‑world drone technology applications.
7. Conclusion
We introduced GNDRL, a deep reinforcement learning framework tailored for multi-UAV dynamic path optimization under energy constraints. By integrating a gated fusion attention mechanism and real‑time battery states into the policy network, our method jointly optimizes task execution and charging decisions. Experimental results across a wide range of problem sizes, battery capacities, and spatial distributions demonstrate that GNDRL significantly reduces total flight distance compared to state-of-the-art DRL baselines and classical metaheuristics, while maintaining competitive runtimes. The framework is highly generalizable, making it a practical and effective solution for urban logistics planning in the era of drone technology. Future work will extend GNDRL to handle dynamic charging station failures and variable payload‑induced energy consumption.