
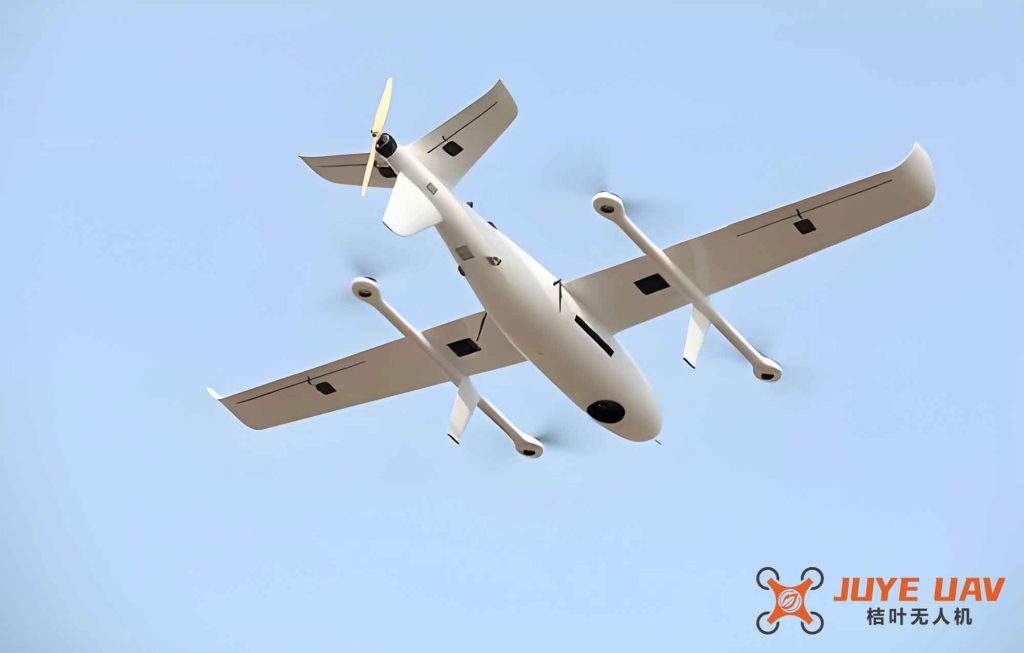
In this study, I investigate the fault diagnosis of fixed-wing drone actuators using a convolutional neural network (CNN) approach. Fixed-wing drones operate under harsh environmental conditions—high temperature, high pressure, strong interference, and strong impacts—which cause actuator faults to exhibit complex, hierarchical, correlated, and uncertain characteristics. Traditional model-based methods require precise mathematical models and struggle with the strong coupling of fixed-wing drone systems. In contrast, deep learning, particularly CNN, offers robust feature learning and expression capabilities. My experiments demonstrate that the proposed CNN method can accurately and reliably identify multiple actuator fault types, significantly enhancing the safety of fixed-wing drone missions.
1. Introduction
Fixed-wing drones are widely used for long-range, long-endurance, and high-altitude missions. However, their actuators are susceptible to various faults due to prolonged exposure to adverse conditions. Reliable fault diagnosis is critical to ensure mission success and safety. Over the years, researchers have explored numerous diagnostic approaches, including model-based and data-driven methods. Model-based approaches, while mature, demand accurate system models that are difficult to construct for highly coupled fixed-wing drone dynamics. With the advent of big data and artificial intelligence, deep learning—especially CNN—has emerged as a powerful tool for fault diagnosis, capable of automatically extracting hierarchical features from raw sensor data.
In this work, I focus on actuator faults of fixed-wing drones, such as efficiency loss and lock-in-place failures. I propose a CNN-based fault diagnostic framework that directly processes time-series flight data. Compared with traditional machine learning methods like support vector machines (SVM), CNN achieves higher accuracy and better generalization when trained on appropriate datasets. I validate the method using real flight data collected under different wind conditions, and I analyze the problem of overfitting when training and testing on different flight scenarios.
2. Convolutional Neural Network Model
The CNN architecture I employ consists of five convolutional layers, five pooling layers, one fully connected hidden layer, and a softmax output layer. Each convolutional layer is followed by a ReLU activation function. The input to the network is a one-dimensional feature vector of length 160, representing the concatenated sensor measurements over 20 consecutive time steps. The kernel size for all convolutional layers is 3×1 with stride 1×1, and the fully connected layer contains 100 neurons.
Convolution Operation: The convolution layer computes feature maps by sliding kernels over the input. For the \(l\)-th layer, the output of the \(i\)-th feature map at position \(j\) is given by:
$$y^{l}(i,j) = K^{l}_i * x^{l}(r_j) = \sum_{j’=0}^{W-1} K^{l}_{i}(j’) \, x^{l}(j+j’)$$
where \(K^{l}_{i}(j’)\) is the \(j’\)-th weight of the \(i\)-th kernel in layer \(l\), \(x^{l}(r_j)\) is the local region being convolved, and \(W\) is the kernel width.
Activation Function: I use the Rectified Linear Unit (ReLU) to introduce nonlinearity. ReLU is defined as:
$$a^{l}(i,j) = f\!\left(y^{l}(i,j)\right) = \max\left\{0, y^{l}(i,j)\right\}$$
ReLU mitigates the vanishing gradient problem and promotes sparse activation, which helps prevent overfitting.
Pooling Operation: Max pooling is applied to reduce the spatial dimensions and provide translation invariance. For pooling region width \(W\), the pooled output is:
$$p^{l}(i,j) = \max_{(j-1)W+1 \le t \le jW} \left\{ a^{l}(i,t) \right\}$$
Fully Connected Layer: The output from the last pooling layer is flattened and fed into a fully connected layer with 100 neurons, followed by ReLU activation. Finally, the softmax layer outputs a probability distribution over the fault classes.
Loss Function: I employ the cross-entropy loss, which for a mini-batch of size \(m\) is:
$$L = -\frac{1}{m} \sum_{k=1}^{m} \sum_{j} p^{j}_k \log(q^{j}_k)$$
where \(p^{j}_k\) is the true label (one-hot encoded) and \(q^{j}_k\) is the predicted probability for class \(j\) of sample \(k\).
3. Fault Modeling and Feature Generation
I consider actuator faults of the fixed-wing drone, including chronic faults, transient faults, and intermittent faults. The fault model is expressed as:
$$u_{\text{app}} = D \, u_{\text{com}} + E$$
where \(u_{\text{com}}\) is the commanded control deflection from the autopilot, and \(u_{\text{app}}\) is the actual applied deflection. The matrix \(D\) models efficiency loss, and the vector \(E\) models bias (e.g., lock-in-place). For the two elevon actuators (right and left), the vector form is:
$$\begin{bmatrix} u_{\text{app1}} \\ u_{\text{app2}} \end{bmatrix} = \begin{bmatrix} d_1 & 0 \\ 0 & d_2 \end{bmatrix} \begin{bmatrix} u_{\text{com1}} \\ u_{\text{com2}} \end{bmatrix} + \begin{bmatrix} e_1 \\ e_2 \end{bmatrix}$$
Here, subscript 1 denotes the right elevon and subscript 2 the left elevon.
Feature Trajectory: To capture temporal dynamics, I construct an input feature vector from the raw sensor measurements. The basic feature set at time \(t\) consists of linear accelerations (\(a_x, a_y, a_z\)), angular rates (\(\omega_x, \omega_y, \omega_z\)), and the two commanded control signals (\(u_{\text{com1}}, u_{\text{com2}}\)):
$$X'(t) = \left[ a_x^t,\; a_y^t,\; a_z^t,\; \omega_x^t,\; \omega_y^t,\; \omega_z^t,\; u_{\text{com1}}^t,\; u_{\text{com2}}^t \right]$$
Concatenating 20 consecutive time steps yields a 160-dimensional input vector:
$$X(t) = \left[ X'(t-19),\; X'(t-18),\; \dots,\; X'(t) \right]$$
The fault classes are defined according to the values of \(d_1\) and \(d_2\) (with \(e_i = 0\) for efficiency loss faults). The following table summarizes the fault codes used in this study:
| Fault Code | Fault Description |
|---|---|
| 0 | Nominal (no fault) |
| 1 | \(d_1 = 0.3\) (right elevon efficiency 30%) |
| 2 | \(d_2 = 0.9\) (left elevon efficiency 90%) |
| 3 | \(d_2 = 0.8\) |
| 4 | \(d_2 = 0.7\) |
| 5 | \(d_2 = 0.6\) |
| 6 | \(d_2 = 0.5\) |
| 7 | \(d_2 = 0.4\) |
| 8 | \(d_2 = 0.3\) |
4. Experimental Setup and Results
Dataset: I use real flight data from a fixed-wing drone (Murat Bronz dataset). The drone specifications are listed below:
| Parameter | Value | Unit |
|---|---|---|
| Wingspan | 1.2 | m |
| Wing area | 0.28 | m² |
| Mass | 0.75 | kg |
| Battery capacity | 30 | Wh |
| Flight time | 60 | min |
Two flights were performed on different days: July 21 with a wind speed of 2.5 m/s, and July 23 with a wind speed of 5.0 m/s. The flight pattern was a figure-eight. Faults were injected sequentially: first three consecutive faults with \(d_1=0.3\), then three consecutive faults with \(d_2=0.9,0.8,\dots,0.3\), each separated by nominal phases.
Evaluation Metrics: I use accuracy, precision, recall, and F1-score to evaluate the diagnostic performance. For multi-class classification, macro-average and weighted-average metrics are reported.
First Experiment – Train and Test on Same Flight (July 21): I split the July 21 data into 80% training and 20% testing. The CNN model achieved 99% accuracy after 50 training epochs. The detailed results are shown in the table below.
| Class | Precision | Recall | F1-score | Support |
|---|---|---|---|---|
| Nominal | 1.00 | 1.00 | 1.00 | 1382 |
| R0.3 | 1.00 | 1.00 | 1.00 | 485 |
| L0.9 | 1.00 | 1.00 | 1.00 | 295 |
| L0.8 | 1.00 | 0.99 | 0.99 | 299 |
| L0.7 | 0.99 | 0.98 | 0.98 | 299 |
| L0.6 | 0.98 | 1.00 | 0.99 | 311 |
| L0.5 | 1.00 | 1.00 | 1.00 | 306 |
| L0.4 | 1.00 | 0.99 | 1.00 | 323 |
| L0.3 | 1.00 | 1.00 | 1.00 | 703 |
| Accuracy | 0.99 | 4403 | ||
| Macro avg | 1.00 | 1.00 | 1.00 | 4403 |
| Weighted avg | 0.99 | 1.00 | 1.00 | 4403 |
To verify the discriminative power of the learned features, I apply t‑SNE to the fully connected layer outputs. The visualization clearly separates all nine fault classes (0 to 8), indicating that the CNN effectively extracts fault-specific patterns from the flight data.
For comparison, I also trained a traditional SVM classifier on the same data. The SVM achieved an accuracy of 93%, as shown below.
| Class | Precision | Recall | F1-score | Support |
|---|---|---|---|---|
| Nominal | 0.92 | 0.98 | 0.94 | 1382 |
| R0.3 | 0.98 | 0.93 | 0.95 | 485 |
| L0.9 | 0.85 | 0.70 | 0.77 | 295 |
| L0.8 | 0.87 | 0.90 | 0.88 | 299 |
| L0.7 | 0.94 | 0.90 | 0.92 | 299 |
| L0.6 | 0.89 | 0.90 | 0.90 | 311 |
| L0.5 | 0.91 | 0.89 | 0.90 | 306 |
| L0.4 | 0.95 | 0.93 | 0.94 | 323 |
| L0.3 | 0.97 | 0.98 | 0.98 | 703 |
| Accuracy | 0.93 | 4403 | ||
| Macro avg | 0.92 | 0.90 | 0.91 | 4403 |
| Weighted avg | 0.93 | 0.93 | 0.93 | 4403 |
Second Experiment – Cross-Day Generalization: I then tested the ability of the CNN to generalize to a different flight day. First, I trained the model on July 21 data (Flight A) and tested on July 23 data (Flight B). The results were disappointing, with overall accuracy around 52%.
| Class | Precision | Recall | F1-score | Support |
|---|---|---|---|---|
| Nominal | 0.89 | 0.57 | 0.70 | 1649 |
| R0.3 | 0.72 | 0.62 | 0.67 | 505 |
| L0.9 | 0.10 | 0.33 | 0.15 | 144 |
| L0.8 | 0.16 | 0.38 | 0.22 | 152 |
| L0.7 | 0.39 | 0.65 | 0.49 | 264 |
| L0.6 | 0.57 | 0.41 | 0.47 | 301 |
| L0.5 | 0.56 | 0.60 | 0.58 | 310 |
| L0.4 | 0.49 | 0.45 | 0.47 | 324 |
| L0.3 | 0.79 | 0.80 | 0.80 | 752 |
| Accuracy | 0.52 | 4401 | ||
| Macro avg | 0.52 | 0.54 | 0.51 | 4401 |
| Weighted avg | 0.70 | 0.59 | 0.62 | 4401 |
The poor performance is attributed to overfitting on the July 21 data, which had lower wind speed (2.5 m/s) compared to the July 23 data (5.0 m/s). The angular rate signals differ significantly under different wind conditions, as illustrated by the raw sensor traces (not shown here). To improve generalization, I reversed the training and testing sets: trained on the more complex July 23 data (higher wind) and tested on July 21 data.
| Class | Precision | Recall | F1-score | Support |
|---|---|---|---|---|
| Nominal | 0.76 | 0.94 | 0.84 | 1382 |
| R0.3 | 0.71 | 0.79 | 0.74 | 485 |
| L0.9 | 0.37 | 0.06 | 0.10 | 295 |
| L0.8 | 0.66 | 0.43 | 0.52 | 299 |
| L0.7 | 0.71 | 0.55 | 0.62 | 299 |
| L0.6 | 0.66 | 0.44 | 0.53 | 311 |
| L0.5 | 0.56 | 0.72 | 0.63 | 306 |
| L0.4 | 0.66 | 0.61 | 0.63 | 323 |
| L0.3 | 0.82 | 0.91 | 0.87 | 703 |
| Accuracy | 0.66 | 4403 | ||
| Macro avg | 0.66 | 0.61 | 0.61 | 4403 |
| Weighted avg | 0.70 | 0.72 | 0.70 | 4403 |
Training on the more challenging data (higher wind) improved the weighted-average F1-score from 0.62 to 0.70. This suggests that exposing the CNN to a wider variety of flight conditions during training helps the model learn more robust features. The low recall for class L0.9 (left elevon 90% efficiency) indicates that detecting subtle faults remains difficult.
Overfitting Mitigation: The cross-day experiment highlights the risk of overfitting when training and testing data come from different distributions. Strategies such as data augmentation, dropout, or training on mixed data from multiple flights could further improve generalization. In this study, I simply reversed the training set to a more diverse condition, which already yielded better results. Future work should incorporate domain adaptation techniques to enhance the fixed-wing drone fault diagnosis system’s robustness.
5. Conclusion
In this paper, I presented a CNN-based fault diagnosis methodology for fixed-wing drone actuators. The proposed network effectively learns spatio-temporal features from raw flight data, achieving 99% accuracy on same-day test data. When applied to cross-day scenarios, the performance degrades due to distribution shift caused by different wind conditions. However, training the model on data from more complex flight conditions (higher wind) significantly improves its generalization ability. The results demonstrate that CNN is a promising tool for fixed-wing drone fault diagnosis, provided the training data are sufficiently representative of the expected operating envelope. Future work will focus on domain adaptation and online learning to realize real-time fault detection for fixed-wing drones in diverse environments.