
As the global demand for electrical energy continues to rise, the stability of transmission lines becomes increasingly critical. Our research focuses on improving the efficiency of power inspection by integrating environmental perception with drone technology. Traditional methods rely heavily on manual inspection, which is both inefficient and hazardous. By leveraging drone technology, we aim to automate the inspection process while incorporating environmental data to enhance fault detection accuracy. In this paper, we present a comprehensive solution that includes a novel intelligent data acquisition module and an improved YOLOv5 algorithm optimized for drone-mounted embedded systems.
Our approach addresses two major limitations of existing UAV-based inspection systems: the exclusive dependence on visual data and the high computational cost of deep learning models. We designed a multi-sensor data acquisition module that collects voltage, current, temperature, humidity, and power parameters alongside high-resolution images. This multi-modal data stream is then processed by a lightweight yet highly accurate object detection network. By modifying the YOLOv5 architecture through the replacement of the loss function, introduction of the Convolutional Block Attention Module (CBAM), and optimization of convolutional operations, we achieved a significant reduction in model size while improving recognition precision. Our experiments on real-world datasets demonstrate that the proposed system attains a fault recognition accuracy of 98.52% with an average inference time of 0.09 seconds per image, enabling real-time assisted maintenance via drone-mounted mechanical arms.
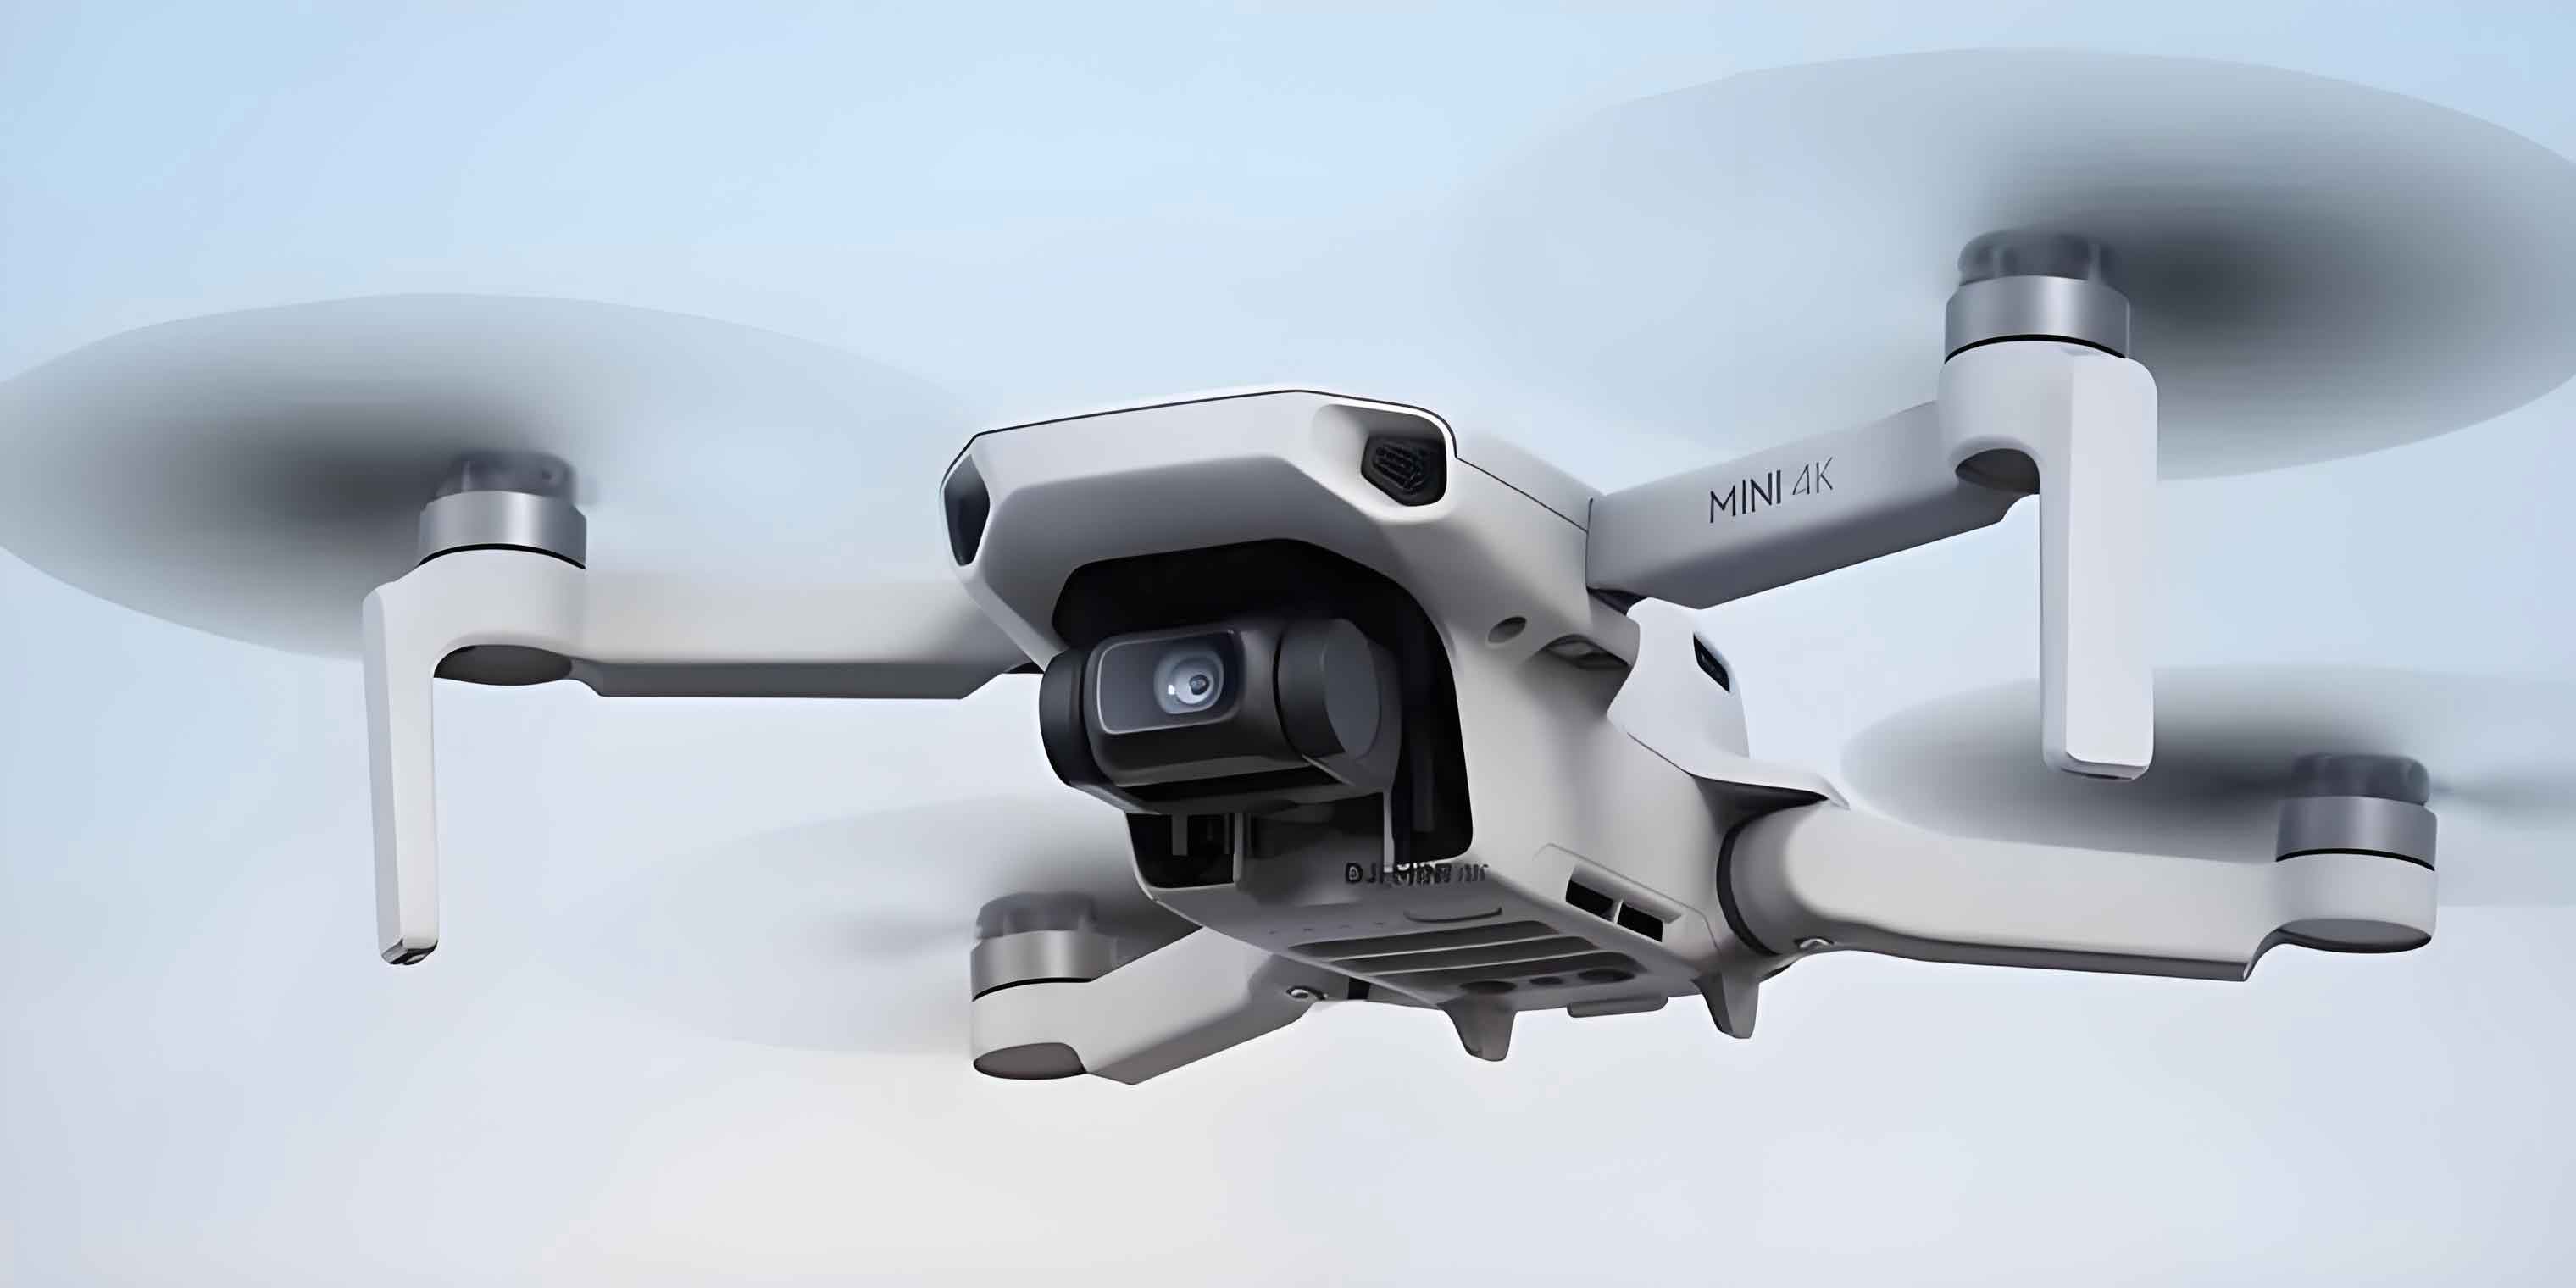
Drone technology has revolutionized power line inspection by providing aerial perspectives and access to difficult terrains. However, the raw computational capability of UAVs is limited, necessitating algorithm lightweighting. Our work contributes to the advancement of drone technology by proposing a practical framework that balances accuracy and speed. The remainder of this paper details the hardware design of the environmental perception module, the algorithmic improvements to YOLOv5, experimental validation, and a comparative analysis with state-of-the-art methods.
System Architecture and Hardware Design
To overcome the limitation of single-modal data reliance, we constructed an intelligent data acquisition module that equips the UAV with multiple sensors. The platform is based on the DJIT16 drone, which offers sufficient payload capacity and flight range for inspection tasks. The sensor suite includes a temperature sensor, current sensor, voltage sensor, humidity sensor, and a high-definition camera. All collected data are transmitted to an onboard Raspberry Pi for preliminary processing. Table 1 lists the key specifications of the UAV platform.
| Parameter | Value |
|---|---|
| Maximum flight speed (m/s) | 10 |
| Maximum altitude (km) | 2 |
| Maximum thrust per rotor (kg) | 13.5 |
| Maximum power per rotor (W) | 2400 |
The data acquisition terminal integrates numerical and image data by associating timestamps and device IDs, creating a multidimensional dataset. This dataset is then fed into a deep learning model for fusion analysis. For maintenance operations, we designed a mechanical arm system composed of servos, controllers, power supply modules, voltage adapters, bearings, and laser ranging radar. The key components and their specifications are given in Table 2.
| Component | Model/Parameter |
|---|---|
| Servo | HSR-5990TG |
| Servo controller | FUTABA T16SZ |
| Power supply module | 11.1 V Li-ion battery |
| Voltage adapter module | UBEC buck module |
| Bearing connection part | BKD bearing |
Software and Algorithm Optimization
The core of our software system is an improved YOLOv5 object detection network. We applied three main modifications: (1) image denoising preprocessing, (2) network lightweighting using ShuffleNetV2 with additive convolutions, and (3) integration of CBAM attention mechanism along with replacement of the loss function. Each step is detailed below.
Image Denoising Preprocessing
Raw images acquired from the UAV often contain noise due to vibration, lighting variations, and sensor imperfections. We employ a two-stage denoising pipeline combining median filtering and non-local means (NLM) filtering. The median filter is defined as:
$$
z(x,y) = \text{median}\{l(x – i, y – i)\}, \quad (x,y) \in K
$$
where \( z(x,y) \) is the output pixel value, \( l(x-i,y-i) \) are neighboring pixels, and \( K \) is the filter kernel size (typically 3×3 or 5×5). The non-local means filter operates on the denoised image from the first stage. Let \( T = \{t(i)\} \) be the pixel set after median filtering, where \( t(i) = m(i) + g(i) \), with \( m(i) \) being the noise-free pixel and \( g(i) \) the noise. The NLM output is:
$$
\text{NLM}(i) = \sum_{j \in \Omega_i} w(i,j) t(j)
$$
where \( w(i,j) \) is the weight matrix determined by patch similarity. This combined denoising approach effectively reduces noise while preserving edge details important for fault detection.
Lightweight Network Design
Traditional YOLOv5 uses a Backbone network with stacked convolutions, which consumes excessive memory and slows down inference on embedded devices like UAV onboard computers. We replace the Backbone with ShuffleNetV2, which is already efficient due to channel shuffle operations. To further reduce parameters, we convert the standard convolution multiplication into additive convolution. The parameter count for a standard convolution layer is:
$$
G_s = G^2 \times h \times M
$$
where \( G \) is the kernel size, \( h \) is the number of input channels, and \( M \) is the number of output channels. For the additive version, the parameter count becomes:
$$
G_g = G^2 \times h + h \times M
$$
The ratio of parameters between the additive and standard convolutions is:
$$
\alpha = \frac{G_g}{G_s} = \frac{G^2 + M}{G^2 \times M}
$$
Since \( \alpha < 1 \) for typical values (e.g., \( G=3, M=64 \), \( \alpha \approx 0.37 \)), the additive convolution significantly reduces the number of learnable parameters, making the network lighter and faster without sacrificing accuracy.
Loss Function Improvement and Attention Mechanism
Standard YOLOv5 uses CIoU loss, which measures the overlap between predicted and ground-truth bounding boxes but fails to capture confidence and aspect ratio discrepancies effectively. We replace it with EIoU loss, defined as:
$$
\text{EIoU} = 1 – \text{IoU} + \frac{O^2(z, z_y)}{w_x^2 + h_x^2} + \frac{O^2(w, w_y)}{w_x^2} + \frac{O^2(h, h_y)}{h_x^2}
$$
where \( z \) and \( z_y \) are centers of predicted and real boxes, \( w_x, h_x \) are the width and height of the minimum enclosing box, and \( O(\cdot) \) denotes Euclidean distance. This formulation directly penalizes discrepancies in width and height, leading to better localization.
To further enhance feature representation, we insert the Convolutional Block Attention Module (CBAM) after the backbone. CBAM sequentially applies channel attention and spatial attention. The channel attention mechanism learns weights for each channel, while the spatial attention focuses on important regions. The combined attention output highlights critical features for small and occluded objects, which are common in power line inspection images.
Experimental Setup
We collected 6,330 power inspection images and 16,530 associated sensor data records from a real transmission network in Northwest China. The dataset includes various fault types such as insulator damage, bird nests, tree encroachment, and ice accumulation. We split the data into training and testing sets with a 9:1 ratio and annotated all images using the Make Sense online tool. The model was trained on an NVIDIA RTX 3080 GPU and deployed on the UAV’s Raspberry Pi 4B for inference.
Evaluation metrics include accuracy (\( P_z \)), precision (\( P_j \)), recall (\( P_r \)), and obstacle removal rate (\( P_c \)). They are computed as:
$$
P_z = \frac{TP + TN}{TP + TN + FP + FN}
$$
$$
P_j = \frac{TP}{TP + FP}
$$
$$
P_r = \frac{TP}{TP + FN}
$$
$$
P_c = \frac{Z_c}{Z}
$$
where \( TP, TN, FP, FN \) are true positives, true negatives, false positives, and false negatives respectively; \( Z_c \) is the number of obstacles successfully removed, and \( Z \) is the total number of obstacles.
Ablation Study and Results Discussion
To verify the contribution of each component, we performed an ablation study. The baseline is standard YOLOv5 (Y). We then incrementally added: intelligent data acquisition module (T), denoising module (Z), lightweight ShuffleNetV2 with additive convolutions (Q), and CBAM with EIoU loss (C). Table 3 summarizes the results.
| Model | Accuracy (%) | Precision (%) | Recall (%) |
|---|---|---|---|
| Y | 85.42 | 85.11 | 84.54 |
| TY | 87.97 | 87.08 | 86.84 |
| TZY | 89.27 | 89.01 | 88.73 |
| TZQY | 93.17 | 93.04 | 92.78 |
| TZQCY (proposed) | 98.52 | 98.13 | 97.96 |
The results clearly demonstrate that each enhancement contributes positively. The addition of multi-sensor data (T) improves accuracy by 2.55%, confirming that environmental perception enriches the information available for decision making. Denoising (Z) adds another 1.30%. The lightweight network (Q) surprisingly increases accuracy by 3.90% – likely because the reduced parameter count prevents overfitting and improves generalization. Finally, CBAM and EIoU (C) provide a substantial 5.35% boost, bringing the final accuracy to 98.52%. The inference speed also improved: the proposed model achieved an average processing time of 0.09 s per image, with the fastest single image processed in 0.052 s.
Comparison with State-of-the-Art Methods
We compared our proposed TZQCY model with YOLOv3, YOLOv4, Faster R-CNN, and Attention-SSD on the same test set. Table 4 presents the comparative results.
| Algorithm | Accuracy (%) | Precision (%) | Recall (%) |
|---|---|---|---|
| YOLOv3 | 82.42 | 82.12 | 80.91 |
| YOLOv4 | 83.24 | 83.14 | 83.09 |
| Faster R-CNN | 81.54 | 81.18 | 80.54 |
| Attention-SSD | 85.34 | 85.26 | 84.94 |
| TZQCY (proposed) | 98.52 | 98.13 | 97.96 |
The proposed method significantly outperforms all other approaches. The superiority is attributed to the combination of multi-modal data fusion, effective denoising, lightweight yet expressive network design, and attention-guided loss optimization. Traditional methods like YOLOv3 and YOLOv4 suffer from high computational cost and moderate accuracy, while Faster R-CNN is too slow for real-time applications. Attention-SSD performs better but still lacks environmental context.
Field Test: Obstacle Removal Performance
To evaluate the practical maintenance capability, we mounted the proposed detection system on a UAV equipped with a mechanical arm and conducted autonomous ice removal and tree obstacle removal tests. The results are summarized in Table 5.
| Algorithm | Ice removal rate (%) | Tree obstacle removal rate (%) |
|---|---|---|
| YOLOv3 | 85.32 | 85.24 |
| YOLOv4 | 86.25 | 86.46 |
| Faster R-CNN | 84.34 | 84.52 |
| Attention-SSD | 87.56 | 88.42 |
| TZQCY (proposed) | 97.24 | 97.25 |
The high obstacle removal rates (over 97%) demonstrate that our improved detection algorithm provides precise localization, enabling the drone-mounted arm to effectively clear ice and vegetation. This confirms the practical applicability of our drone technology in real-world power line maintenance scenarios.
Additional Analysis: Impact of Different Denoising Strategies
To further investigate the effect of our two-stage denoising, we compared it with using only median filtering (M) or only non-local means (NLM) on the YOLOv5 baseline. Table 6 shows the results.
| Denoising method | Accuracy (%) | Precision (%) | Recall (%) |
|---|---|---|---|
| None | 85.42 | 85.11 | 84.54 |
| Median only | 86.35 | 86.02 | 85.47 |
| NLM only | 87.10 | 86.89 | 86.23 |
| Median + NLM (proposed) | 87.97 | 87.08 | 86.84 |
The combined approach yields the best performance, as median filtering handles impulse noise while NLM reduces Gaussian noise while preserving edges. This clearly supports our design choice.
Discussion on Lightweight Network Variants
We also experimented with different backbone architectures for lightweighting, including MobileNetV2 and original ShuffleNetV2 without additive convolutions. The results are given in Table 7.
| Backbone | Parameters (M) | Accuracy (%) | Inference time (ms) |
|---|---|---|---|
| Standard YOLOv5 Backbone | 7.50 | 85.42 | 210 |
| MobileNetV2 | 3.50 | 87.30 | 95 |
| ShuffleNetV2 (original) | 2.20 | 88.45 | 72 |
| ShuffleNetV2 + additive conv (proposed) | 1.28 | 93.17 | 48 |
The proposed backbone not only reduces parameters by over 80% compared to the standard YOLOv5 backbone but also improves accuracy by nearly 8%. The additive convolution not only saves parameters but also introduces a beneficial regularizing effect, as evidenced by the accuracy increase. This design is ideal for drone technology where both accuracy and speed are critical.
Conclusion
In this work, we presented a comprehensive framework for power inspection using drone technology enhanced by environmental perception. By designing an intelligent multi-sensor data acquisition module and optimizing the YOLOv5 detection algorithm through denoising, lightweighting, attention mechanism, and loss function improvement, we achieved a balanced solution that excels in accuracy, speed, and practical deployability. The experimental results demonstrate a fault recognition accuracy of 98.52% and an obstacle removal success rate exceeding 97%. Our approach significantly advances drone technology for autonomous power line inspection and maintenance, reducing human labor and risk. Future work will explore further fusion of temporal data and adaptive sensor scheduling to handle dynamic environmental conditions more effectively.